본문으로 건너뛰기

Full Stack JavaScript Developer | Half-time Open Sourcerer.

모든 저자 보기

IAI +005

· 약 13분

Neural Network Development History​

  • 1950s-1960s: Early Foundations
    • McCulloch & Pitts (1943): mathematical neuron model
    • Rosenblatt's Perceptron (1958): first trainable network
    • Minsky & Papert (1969): limitations (XOR problem) → AI Winter
  • 1970s–1980s: First Revival
    • Werbos (1974); Rumelhart, Hinton, Williams (1986): Backpropagation
    • Hopfield Networks (1982): associative memory
    • Renewed optimism but limited by hardware
  • 1990s: Consolidation
    • LeCun's CNN (LeNet, 1989): digit recognition
    • Elman, Jordan: Recurrent Neural Networks
    • Symbolic AI still dominated mainstream
  • 2000s: Deep Learning Foundations
    • Better hardware (GPUs) + large datasets
    • Hinton (2006): Deep Belief Networks (unsupervised pretraining)
    • Connectionism regains attention
  • 2010s: Deep Learning Boom
    • ImageNet (2012): AlexNet breakthrough
    • RNNs, LSTMs, GRUs → speech & translation
    • Transformers (2017): revolutionized NLP
  • 2020s: Scaling & Foundation Models
    • Large Language Models (GPT, BERT, etc.)
    • Multimodal AI: vision, text, speech integration
    • Connectionism dominates AI research & industry

Neural Network Models​

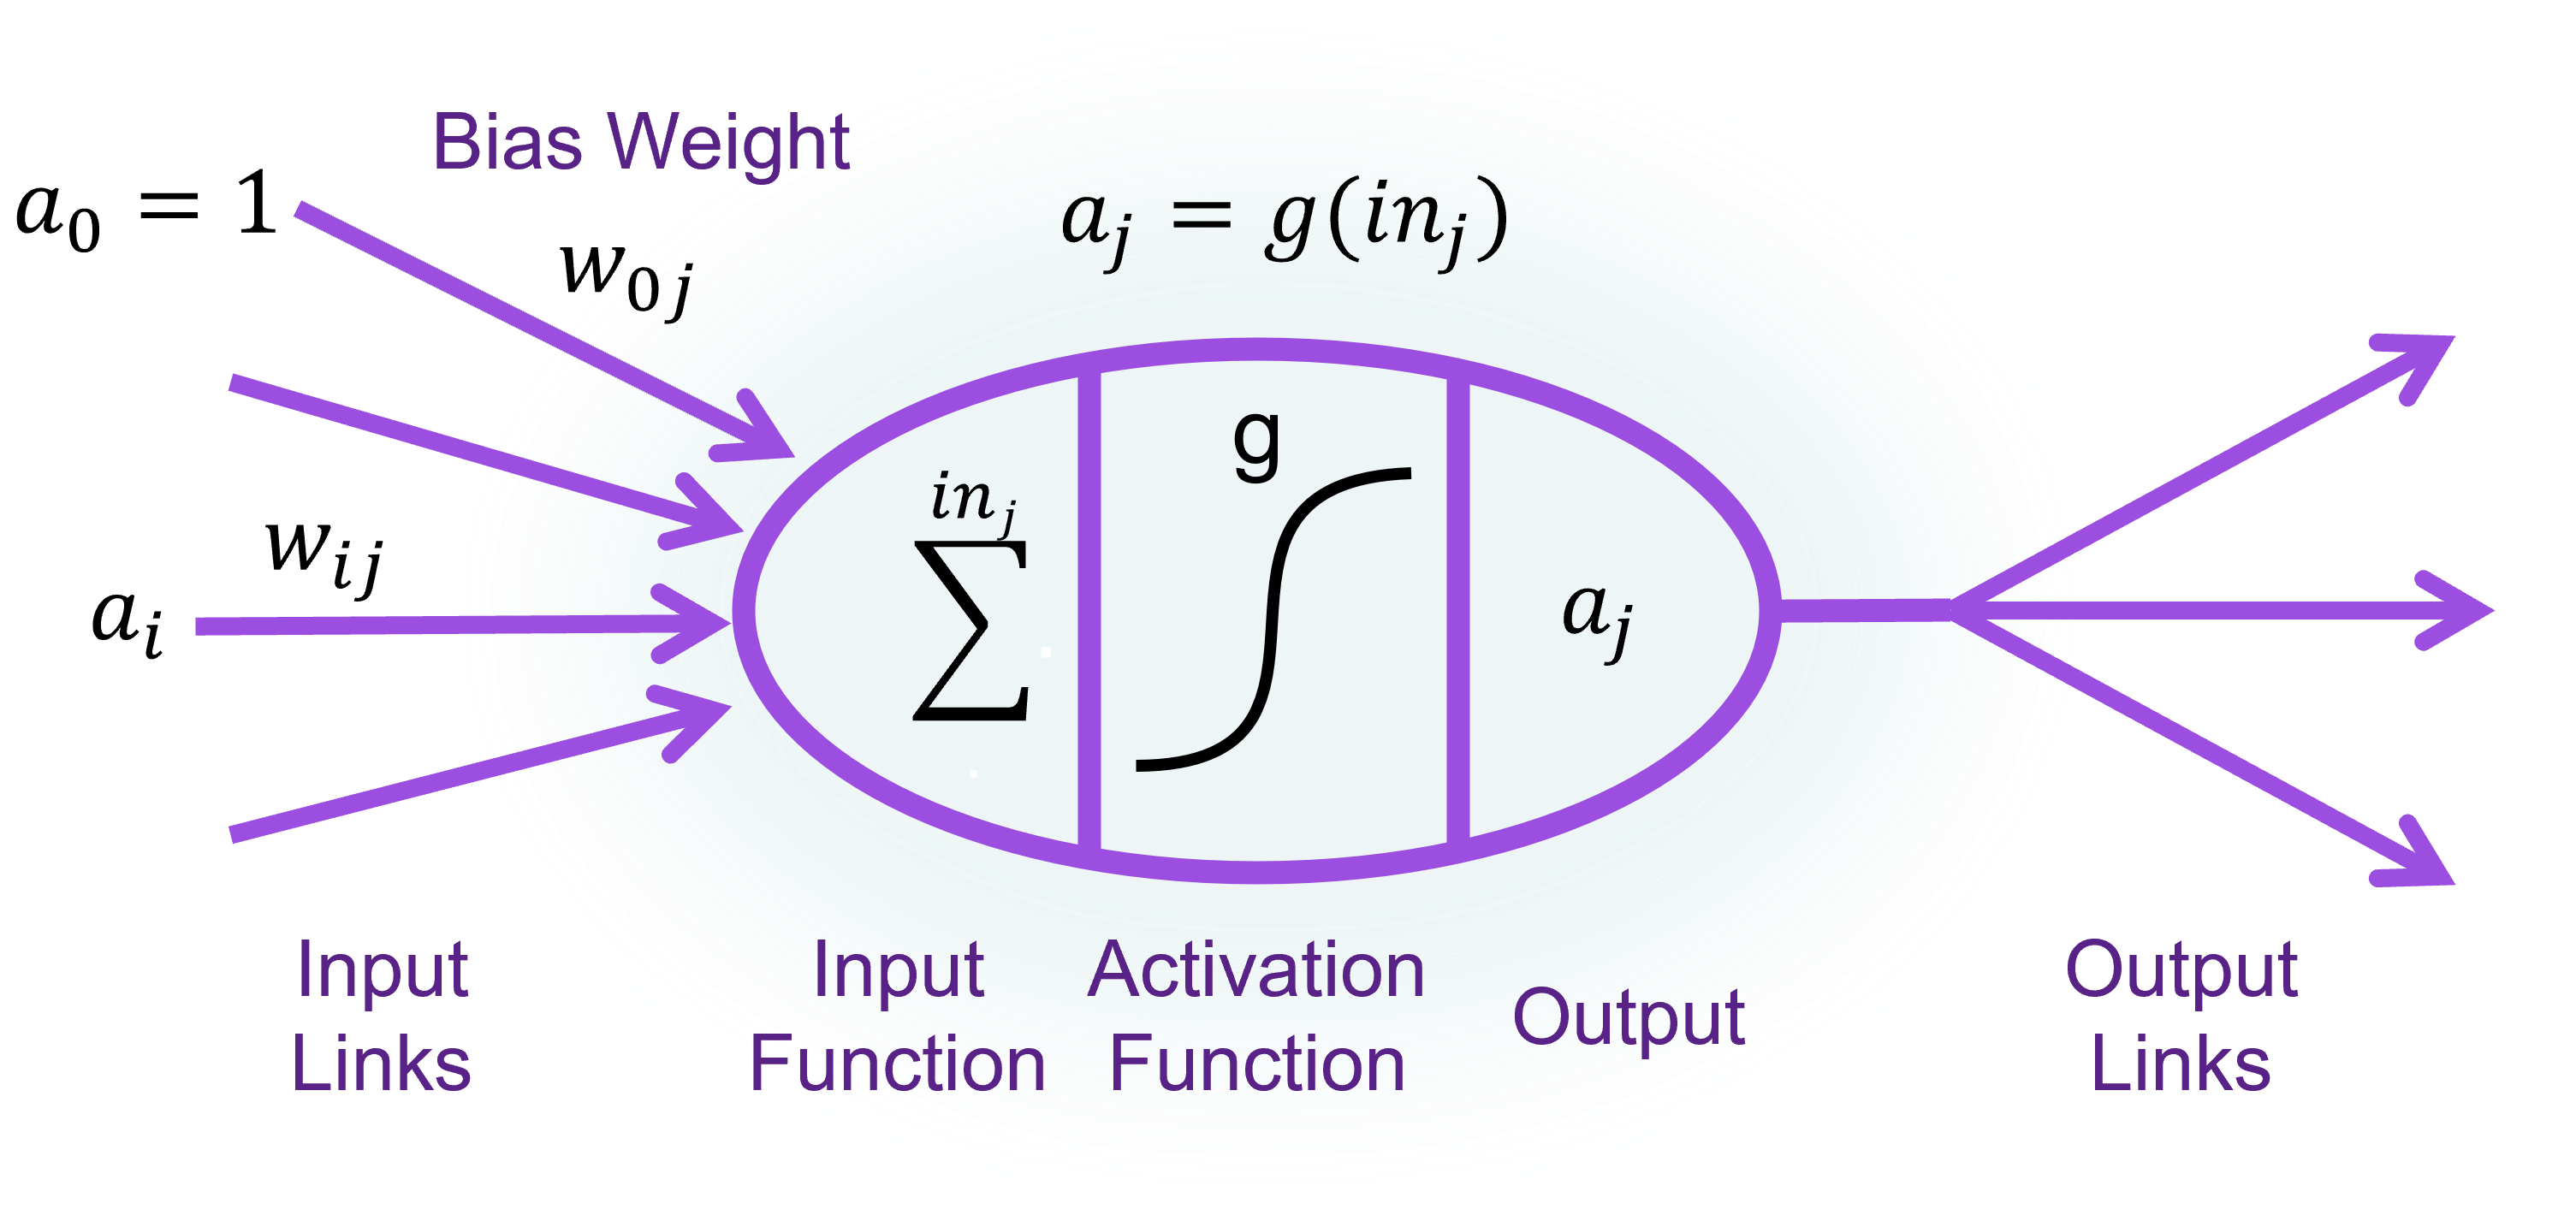
  • a collection of units (neurons) connected together
  • The properties of the network are determined by its topology and the properties of the neurons.
  • Roughly speaking, the neuron fires when a linear combination of its inputs exceeds some (hard or soft) threshold.
Simple Neuron

  • inj=∑i=0nwijaiin_j = \sum_{i=0}^{n} w_{ij}a_i
  • outj=g(inj)out_j = g(in_j)
  • aj=g(∑i=0nwijai)a_j = g(\sum_{i=0}^{n} w_{ij} a_i)

Activation function​

ReLU function​

ReLU(x)=max(0,x)ReLU(x) = max(0, x)

  • an abbreviation for rectified linear unit
  • Commonly used

Softplus function​

Softplus(x)=log⁡(1+ex)Softplus(x) = \log(1 + e^x)

  • A smooth version of the ReLU function

Logistic or Sigmoid function​

Logistic(x)=11+e−xLogistic(x) = \frac{1}{1 + e^{-x}}

  • Non-linear, can represent a nonlinear function

Tanh function​

tanh(x)=e2x−1e2x+1tanh(x) = \frac{e^{2x} -1}{e^{2x} + 1}

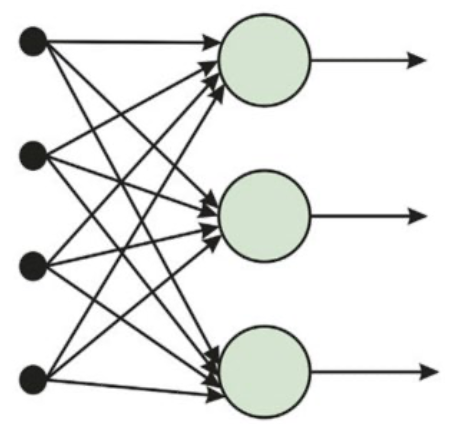
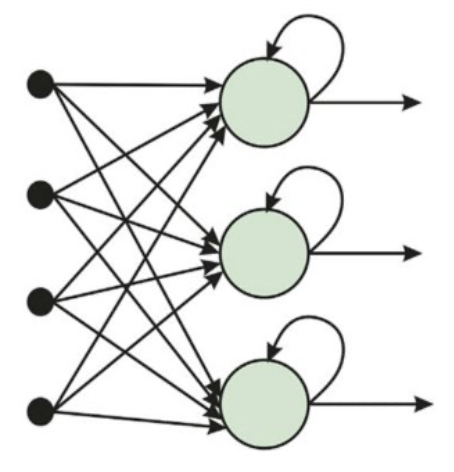
Topology of a neural network​

  • Feed-forward network (FFN):
    • Every node receives inputs from "upstream" nodes and delivers output to "downstream" nodes.
    • There are no loops.
    • FFN represents a function of its current inputs, thus it has no internal state other than the weights themselves.
  • Recurrent Network (RNN):
    • A recurrent network feeds its outputs back into its own inputs.
    • In a recurrent network, the neuron values can eventually settle down, keep cycling, or behave unpredictably.
    • can support short-term memory
FFNRNN
FFNRNN

Training Process​

  • Go through each training sample.
  • If correctly classified → do nothing.
  • If misclassified → update the weights:
  • wi←wi+α(y−y^)xiw_i \leftarrow w_i + \alpha(y - \hat{y})x_i

Perceptron for Binary Classification​

  • A perceptron separates data into two classes with a hyperplane.
  • if w⋅x≥0→1w \cdot x \geq 0 \rightarrow 1
  • if w⋅x≤0→0w \cdot x \le 0 \rightarrow 0

Learning Rules​

AspectPerceptron Learning RuleGradient Descent (with Sigmoid)
Activation functionHard threshold (계단 함수)
Threshold(z)=1  if  z≥0,  0  otherwiseThreshold(z) = 1 \; \text{if} \; z \ge 0,\; 0 \; \text{otherwise}
Sigmoid (연속 함수)
hw(x)=11+e−w⋅xh_w(x) = \frac{1}{1+e^{-w \cdot x}}
Output0 또는 10과 1 사이의 실수 값
Loss function없음 (틀리면 조정, 맞으면 유지)
규칙 기반 학습
L=(y−hw(x))2L = (y - h_w(x))^2 (L2 loss)
또는 Cross-Entropy (실무에서 자주 사용)
Update rule틀렸을 때만:
w←w+α(y−hw(x))xw \leftarrow w + \alpha (y - h_w(x))x
경사하강법:
w←w+α(y−hw(x))⋅hw(x)(1−hw(x))⋅xw \leftarrow w + \alpha (y - h_w(x)) \cdot h_w(x)(1-h_w(x)) \cdot x
Why derivative?Hard threshold는 미분 불가능 → 단순 규칙 사용Sigmoid는 연속적이고 미분 가능 → Loss 함수의 기울기(gradient)를 따라 업데이트.
여기서 hw(x)(1−hw(x))h_w(x)(1-h_w(x)) 항은 sigmoid의 도함수에서 나온 것.
Interpretation틀리면 정답 방향으로 한 걸음 이동Loss가 줄어드는 방향으로 점진적으로 이동

Feadforward NN, FNN​

  • a multilayer perceptron network
  • one input layer, N hidden layers, N >= 1, and one output layer.
  • Except for the input layer, each layer has a same activation function g.
  • The final output is represented by a vector function of inputs and weights.
  • If it has three layers, Shallow Neural Network, otherwise Deep Neural Network.

Traning a FNN​

  • Forward
    • Activation passing from the input layer to the output layer
    • Calculate the output
  • Backward
    • Errors propagating backward from the output layer to the input layer
    • Update weights

Forward phase​

  • Activation of each node is computed in two steps:

    1. Weighted sum (in): sum of activations from the previous layer, multiplied by weights.
    2. Apply activation function g: pass the weighted sum through g to produce the node's activation.
  • Process: propagate activations layer by layer towards the output layer.

  • Output value (example with 2 layers):

    • hw(x)=g(2)(W(2)g(1)(W(1)x))h_w(x) = g^{(2)}\big(W^{(2)} g^{(1)}(W^{(1)} x)\big)

Backward phase​

  • Loss function: choose squared error loss (L2)
    • L2(y,y^)=(y−y^)2L_2(y, \hat{y}) = (y - \hat{y})^2
  • Prediction:
    • y^=hw(x)\hat{y} = h_w(x)
  • Gradient descent: compute gradient of the loss with respect to weights, then update weights along the negative gradient direction.
    • wi,j←wi,j−α⋅gradientwi,jw_{i,j} \leftarrow w_{i,j} - \alpha \cdot gradient_{w_{i,j}}
  • Example: sigmoid activation:
    • y^=11+e−w⋅x\hat{y} = \frac{1}{1 + e^{-w \cdot x}}
    • Gradient of the loss:
      • gradientwi,j=∂∂wi,jLoss(hw)=2(y−hw(x))⋅(−∂∂wi,jhw(x))gradient_{w_{i,j}} = \frac{\partial}{\partial w_{i,j}} Loss(h_w) = 2 (y - h_w(x)) \cdot \Big(- \frac{\partial}{\partial w_{i,j}} h_w(x)\Big)
    • Chain rule applied:
      • ∂g(f(x))∂x=g′(f(x))⋅f′(x)\frac{\partial g(f(x))}{\partial x} = g'(f(x)) \cdot f'(x)
  • Example: Gradient derivation for sigmoid
    • Weighted input
      • W⋅X=w1,3x1+w2,3x2+w0,3x0W \cdot X = w_{1,3}x_1 + w_{2,3}x_2 + w_{0,3}x_0
      • (where x0=1x_0 = 1 for the bias)
    • Gradient of the loss
      • gradientwi,j=∂∂wi,jLoss(hw)=2(y−hw(x))⋅(−∂∂wi,jhw(x))gradient_{w_{i,j}} = \frac{\partial}{\partial w_{i,j}} Loss(h_w) = 2 (y - h_w(x)) \cdot \Big(-\frac{\partial}{\partial w_{i,j}} h_w(x)\Big)
    • Derivative of sigmoid output
      • ∂∂wi,jhw(x)=hw(x)(1−hw(x))⋅∂∂wi,j(W⋅X)\frac{\partial}{\partial w_{i,j}} h_w(x) = h_w(x)(1 - h_w(x)) \cdot \frac{\partial}{\partial w_{i,j}} (W \cdot X)
        • ∂∂wi,j(11+e−WX)\frac{\partial}{\partial w_{i,j}} \left( \frac{1}{1 + e^{-W X}} \right)
        • =(11+e−WX)(1−11+e−WX)⋅∂∂wi,j(WX)= \left( \frac{1}{1 + e^{-W X}} \right) \left(1 - \frac{1}{1 + e^{-W X}} \right) \cdot \frac{\partial}{\partial w_{i,j}} (W X)
        • =hw(x)(1−hw(x))⋅∂∂wi,j(WX)= h_w(x) \big(1 - h_w(x)\big) \cdot \frac{\partial}{\partial w_{i,j}} (W X)
    • Derivative of weighted input
      • ∂∂w0,3(W⋅X)=x0=1\frac{\partial}{\partial w_{0,3}}(W \cdot X) = x_0 = 1
      • ∂∂w1,3(W⋅X)=x1\frac{\partial}{\partial w_{1,3}}(W \cdot X) = x_1
      • ∂∂w2,3(W⋅X)=x2\frac{\partial}{\partial w_{2,3}}(W \cdot X) = x_2
    • Weight update rule
      • General form: wi,j←wi,j−α⋅gradientwi,jw_{i,j} \leftarrow w_{i,j} - \alpha \cdot gradient_{w_{i,j}}
      • w0,3←w0,3+α(y−hw(x))hw(x)(1−hw(x))w_{0,3} \leftarrow w_{0,3} + \alpha (y - h_w(x)) h_w(x)(1 - h_w(x))
      • w1,3←w1,3+α(y−hw(x))hw(x)(1−hw(x))x1w_{1,3} \leftarrow w_{1,3} + \alpha (y - h_w(x)) h_w(x)(1 - h_w(x)) x_1
      • w2,3←w2,3+α(y−hw(x))hw(x)(1−hw(x))x2w_{2,3} \leftarrow w_{2,3} + \alpha (y - h_w(x)) h_w(x)(1 - h_w(x)) x_2

Backward phase Steps​

  1. Select a loss function
    • For example, squared error loss:
    • L(y,y^)=(y−y^)2,y^=hw(x)L(y, \hat{y}) = (y - \hat{y})^2, \quad \hat{y} = h_w(x)
  2. Choose an activation function
    • Suppose we use a sigmoid:
    • hw(x)=11+e−W⋅Xh_w(x) = \frac{1}{1 + e^{-W \cdot X}}
  3. Calculate the error at the output node
    • The delta (error term) at the output is
    • Δout=2(y^−y)⋅g′(inout)\Delta_{out} = 2(\hat{y} - y) \cdot g'(in_{out})
  4. Calculate the error at hidden nodes
    • A hidden unit may connect to multiple nodes in the next layer.
    • Therefore, its error is the weighted sum of all deltas it feeds into, scaled by its own derivative:
    • Δi=g′(ini)∑jwi,jΔj \Delta_i = g'(in_i) \sum_j w_{i,j} \Delta_j
    • The summation appears because the hidden node's output influences several downstream nodes, and all those error signals must be aggregated.
  5. Update the weights with gradient descent
    • The gradient with respect to weight wi,jw_{i,j} is simply the input times the delta:
    • ∂L∂wi,j=aiΔj\frac{\partial L}{\partial w_{i,j}} = a_i \Delta_j
    • Update rule:
    • wi,j←wi,j−α aiΔjw_{i,j} \leftarrow w_{i,j} - \alpha \, a_i \Delta_j

Vanishing gradient​

  • The error signal are extinguished altogher as they are propagated back through the network
  • In deep feedforward networks with sigmoid/tanh, repeated multiplication of small derivatives (0<g′(z)<10 < g'(z) < 1) during backpropagation causes the gradient to vanish.

Optimizer​

  • Training a neural network consists of modifying the network's parameters, minimizing the loss function on the training set.
  • any kind of optimization algorithm could be used.
  • modern neural networks are almost always trained with some variant of stochastic gradient descent (SGD). Adam Optimizer
  • The optimiser is specified in the compilation step with tensorflow.

Recurrent NN, RNN​

  • units may take as input a value computed from their own output at an earlier step in the computation.
  • have internal state, or memory: inputs received at earlier time steps affect the RNN's response to the current input.
  • be used to perform more general computations.
    • to analyze sequential data in which a new input vector xtx_t arrives at each time step
  • Markov assumption: the hidden state ztz_t of the network suffices to capture the information from all previous inputs.
    • zt=f(zt−1,xt)z_t = f(z_{t-1}, x_t)
    • Once trained, this function represents a time-homogeneous process
    • The same update rule fwf_w applies at every time step, regardless of whether it’s the first input or the hundredth.
  • RNNs are designed for sequential data.
  • a hidden state that captures information from previous steps.
  • suffer from vanishing/exploding gradients.
  • Good for short-term dependencies.

Backpropagtion Through Time, BPTT​

  • gradient expression is recursive.
    • ∂zt∂wz,z\frac{\partial z_t}{\partial w_{z,z}}
    • =∂∂wz,zgz(inz,t)= \frac{\partial}{\partial w_{z,z}} g_z(in_{z,t})
    • =gz′(inz,t)∂inz,t∂wz,z= g_z'(in_{z,t}) \frac{\partial in_{z,t}}{\partial w_{z,z}}
    • =gz′(inz,t)∂∂wz,z(wz,zzt−1+wx,zxt+w0,z)= g_z'(in_{z,t}) \frac{\partial}{\partial w_{z,z}} (w_{z,z} z_{t-1} + w_{x,z} x_t + w_{0,z})
    • =gz′(inz,t)(zt−1+wz,z∂zt−1∂wz,z)= g_z'(in_{z,t}) \left( z_{t-1} + w_{z,z} \frac{\partial z_{t-1}}{\partial w_{z,z}} \right)
      • ∂zt∂Wz,z\frac{\partial z_t}{\partial W_{z,z}} includes ∂zt−1∂Wz,z\frac{\partial z_{t-1}}{\partial W_{z,z}}
  • the gradient with run time being linear in the size of the network
  • handled automatically by deep learning software systems.
  • Iterating the recursion shows that the gradient at time TT includes a term proportional to:
    • wz,z∏t=1Tgz′(inz,t)w_{z,z} \prod_{t=1}^{T} g'_z(in_{z,t})
  • Since for sigmoid, tanh, and ReLU we have g′≤1g' \leq 1, if wz,z<1w_{z,z} < 1 the RNN will suffer from the vanishing gradient problem.
  • If wz,z>1w_{z,z} > 1, we may encounter the exploding gradient problem.

Long Short-Term Memory, LSTM​

  • memory cell is essentially copied from time step to time step.
  • New information enters the memory by adding updates.
    • the gradient expressions do not accumulate multiplicatively over time.
  • include gating units: vectors control the flow of information in the LSTM, elementwise multiplication of the corresponding information vector.
  • a type of RNN designed to overcome vanishing gradient.
  • use gates (input, forget, output) to control information flow.
  • Capable of learning long-term dependencies.
  • Widely used in NLP, speech recognition, and time series forecasting.

Gates in LSTM​

  • Forget gate: decides what information to discard from the cell state.
  • Input gate: decides what new information to store in the cell state.
  • Output gate: decides what information to output from the cell state.
    • similar role to the hidden state in basic RNNs.
  • Update equations:
    • ft=σ(Wx,fxt+Wz,fzt−1)f_t = \sigma(W_{x,f}x_t + W_{z,f}z_{t-1})
      • Decides which parts of the previous cell state ct−1c_{t-1} should be kept or discarded.
    • it=σ(Wx,ixt+Wz,izt−1)i_t = \sigma(W_{x,i}x_t + W_{z,i}z_{t-1})
      • Determines how much of the new information from the current input xtx_t and the previous hidden state zt−1z_{t-1} should be added.
    • ot=σ(Wx,oxt+Wz,ozt−1)o_t = \sigma(W_{x,o}x_t + W_{z,o}z_{t-1})
      • Controls which parts of the current cell state ctc_t are exposed as the hidden state ztz_t.
    • ct=ct−1⊙ft+it⊙tanh(Wx,Cxt+Wz,Czt−1)c_t = c_{t-1} \odot f_t + i_t \odot \text{tanh}(W_{x,C}x_t + W_{z,C}z_{t-1})
      • Cell state update
      • Past information (ct−1c_{t-1}) is partially retained through the forget gate.
      • New information is added through the input gate and tanh⁡\tanh.
      • Thus, ctc_t serves as the long-term memory of the LSTM.
    • zt=ot⊙tanh(ct)z_t = o_t \odot \text{tanh}(c_t)
      • Hidden state update
      • The cell state is normalized with tanh⁡(ct)\tanh(c_t) and filtered by the output gate.
      • ztz_t is the hidden state passed forward to the next time step.

Gated Recurrent Unit, GRU​

  • Variant of RNN with gating mechanisms.
  • Designed to capture long-term dependencies without complex architecture.
  • a simpler alternative to LSTMs. (lightweight, effective RNN variant)
  • Captures temporal dependencies (short & long).
  • Combine input and forget gates into a single update gate.
  • Require fewer parameters than LSTM, making them faster to train.
  • Perform comparably to LSTMs in many tasks.
  • Prevents vanishing gradient.
  • Good balance between complexity & performance.
  • Excels in time series forecasting tasks.
  • Widely used in finance, energy and IoT.

Gates in GRU​

  • Update gate (z): decides how much past information to keep
  • Reset Gate (r): decides how much past information to forget
  • Candidate hidden state (h~\tilde{h}): potential new memory
  • Final hidden state (hh): weighted combination of old and new information.

GRU Workflow​

  • Reset gate (rr)
    • Controls how much of the previous hidden state should be "forgotten."
    • A small value means most of the past memory is erased, while a large value means much of it is retained.
  • Update gate (zz)
    • Acts as a switch to decide whether to keep the previous state hprevh_{prev} or replace it with the new candidate h~\tilde{h}.
    • If z=1z=1, the past is fully kept; if z=0z=0, it is completely replaced by the new candidate.
  • Candidate state (h~\tilde{h})
    • Combines the current input xtx_t with the reset-gated previous hidden state to generate the "candidate" new information.
  • Final hidden state (hh)
    • Blends the past and the candidate using the update gate zz.
    • If zz is large → the past memory dominates.
    • If zz is small → the new candidate dominates.
  • h=(1−z)h~+zhprevh=(1−z)\tilde{h}+zh_{prev}

Comparison: RNN vs LSTM vs GRU​

AttributeRNNLSTMGRU
ArchitectureSimple, hidden stateComplex, memory cell + 3 gatesSimplified, 2 gates (update/reset)
Information FlowStored in hidden stateControlled by gatesControlled by merged gates
Long-term DependencyWeak (vanishing gradient)Strong (gates solve vanishing gradient)Strong (gates solve vanishing gradient)
Short-term DependencyStrongStrongStrong
Number of ParametersFewManyFewer than LSTM
Training SpeedFastSlowFast
PerformanceGood for short-termGood for long-termEfficient, similar to LSTM
Application AreasSimple time series, basic NLPNLP, speech, time series forecastingFinance, IoT, energy, time series
Vanishing GradientYesNoNo
Typical Use CasesText generation, simple predictionTranslation, speech recognitionTime series prediction, sensor data
SimplicityVery simple, rarely usedMore complex, expressive (3 gates)Simpler than LSTM, fewer parameters
ExpressivenessLimited, struggles with long-termHigh, handles very complex sequencesModerate, good for moderate data size
Training EfficiencyFast, but limitedSlower, better for complex dataFast, efficient, similar performance
Trade-offSimple but weak for long-termCapacity for complex, long sequencesSimplicity vs. capacity

Open X-Embodiment review

· 약 5분

RT-X​

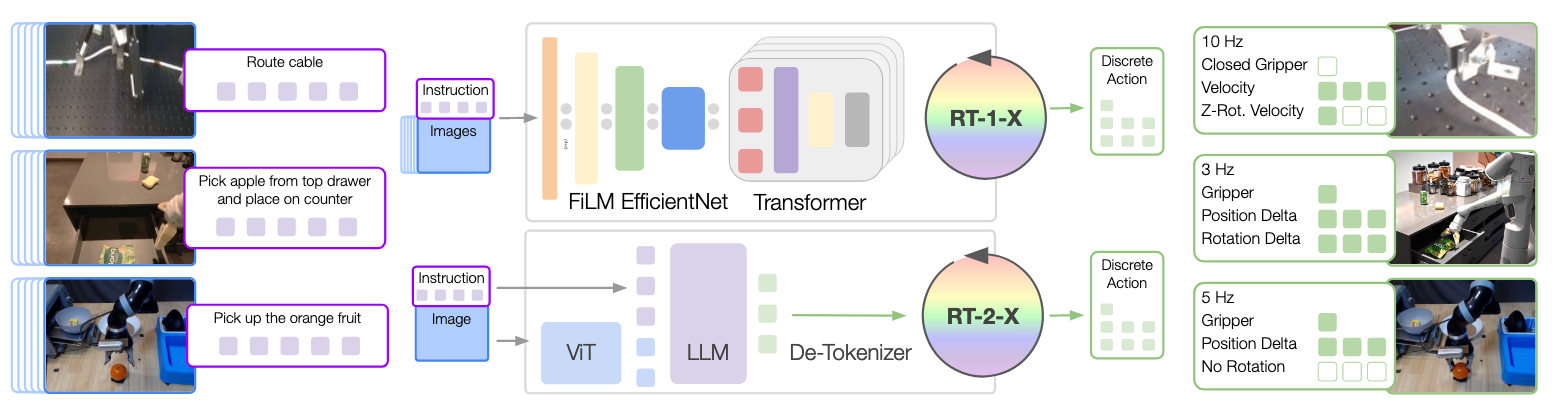
  • RT-X trains generalist robot policies by co-training RT-1/RT-2 on an X-embodiment mix of multi-robot, multi-task data, enabling efficient adaptation to new robots, tasks, and environments.
  • It standardizes 1M+ trajectories from 22 embodiments into the Open X-Embodiment (RLDS/tfrecord) repository, unifying observations and 7-DoF actions via coarse alignment.
  • Experiments show strong positive transfer and emergent skills (≈3× with RT-2-X on cross-robot tasks); performance scales with model capacity, short image histories, and web pretraining, while sensing/actuation diversity and frame alignment remain open problems.

RT-X Architecture

Motivation​

  • Seeks a generalist X-robot policy that can be efficiently adapted to new robots, tasks, and environments.
  • Mirrors a trend from CV/NLP where general-purpose, web-scale pretrained models outperform narrow, task-specific models.
  • Robotics lacks comparably large, diverse interaction datasets, making direct transfer of these lessons challenging.

Objectives​

  1. Positive transfer: Test whether co-training on data from many robots improves performance on each training domain.
  2. Ecosystem building: Organize large robotic datasets to enable future X-embodiment research.

Core Approach​

  • Train RT-1 and RT-2 on data from 9 different manipulators, producing RT-X variants that outperform policies trained only on the evaluation domain and show better generalization and new capabilities.

What’s Different From Prior Transfer Methods​

  • Many prior works reduce the embodiment gap via specialized mechanisms (shared action spaces, representation learning objectives, policy adaptation using embodiment metadata, decoupled robot/environment representations, domain translation).
  • RT-X directly trains on X-embodiment data without explicit gap-reduction machinery and still observes positive transfer.

Dataset & Format (Open X-Embodiment)​

  • 1M+ real robot trajectories, 22 embodiments (single-arm, bimanual, quadrupeds), pooled from 60 datasets / 34 labs, standardized for easy use.
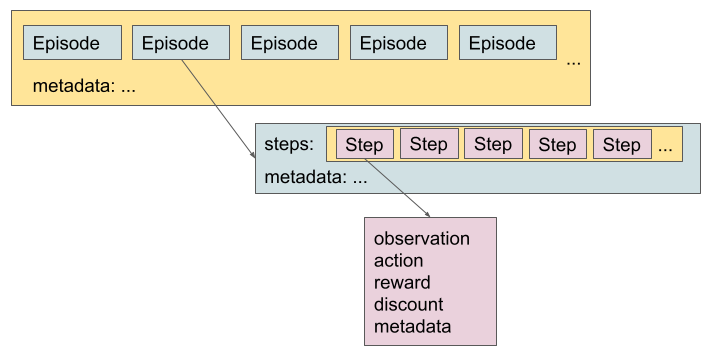
  • Uses RLDS (serialized tfrecord), supporting varied action spaces and input modalities (RGB, depth, point clouds), and efficient parallel loading across major DL frameworks.
  • Language annotations are leveraged; PaLM is used to extract objects/behaviors from instructions.

RLDS

Data Format Consolidation (Coarse Alignment)​

  • Observations: History of recent images + language instruction. One canonical camera view per dataset is resized to a common resolution.
  • Actions: Convert original controls to a 7-DoF end-effector vector (x, y, z, roll, pitch, yaw, gripper or their rates). Actions are normalized before discretization; outputs are de-normalized per embodiment.
  • Deliberate non-alignment: Camera poses/properties are not standardized; action frame alignment across datasets is not enforced. The same action vector may cause different motions on different robots (absolute/relative, position/velocity allowed).

Policy Architectures​

  • RT-1 (≈35M params): Transformer for control. Inputs: 15-frame image history + natural-language instruction.
    • Vision via ImageNet-pretrained EfficientNet; language via USE embedding.
    • Fuse via FiLM → 81 vision–language tokens → decoder-only Transformer outputs tokenized actions.
  • RT-2 (VLA family): Internet-scale VLM co-fine-tuned to output action as text tokens (e.g., 1 128 91 241 5 101 127).
    • Any pretrained VLM can be adapted; this work uses RT-2–PaLI-X (ViT backbone + UL2 LM; primarily pretrained on WebLI).

Training Setup​

  • Robotics data mixture: Data from 9 manipulators (a union of multiple well-known robotics datasets).
  • Loss: Standard categorical cross-entropy over tokenized actions.
  • Regimes:
    • RT-1-X: Trained solely on the robotics mixture.
    • RT-2-X: Co-fine-tuned on a ~1:1 mix of original VLM data and the robotics mixture.

Experimental Questions​

  1. Does X-embodiment co-training improve in-domain performance (positive transfer)?
  2. Does it improve generalization to unseen tasks?
  3. How do model size, architecture, and dataset composition influence performance/generalization?

Key Results​

  • Small-scale domains: RT-1-X outperforms the Original Method (the authors’ per-dataset baselines) on 4/5 datasets with a large average gain → limited data domains benefit greatly from X-embodiment co-training.
  • Large-scale domains:
    • RT-1-X does not beat an RT-1 trained only on the embodiment-specific large dataset (suggests underfitting for this class).
    • RT-2-X (larger capacity) outperforms both Original Method and RT-1 → X-robot training helps even in data-rich regimes when using sufficient capacity.

Generalization & Emergent Skills​

  • Unseen objects/backgrounds/environments: RT-2 and RT-2-X perform on par (VLM backbone already strong here).
  • Emergent skills (transfer across robots): On Google Robot tasks that do not appear in RT-2’s dataset but exist in Bridge (for WidowX), RT-2-X ≈ 3× RT-2.
    • Removing Bridge from RT-2-X training significantly reduces hold-out performance → skills likely transferred from WidowX data.

Design Insights (Ablations)​

  • Short image history notably improves generalization.
  • Web pretraining is critical for large models’ high performance.
  • Model capacity matters: 55B model succeeds more than 5B on emergent skills → greater capacity ⇒ greater cross-dataset transfer.
  • Co-fine-tuning vs. fine-tuning: Similar performance in this study (attributed to the greater diversity of robotics data in RT-2-X vs. prior works).

Limitations (Open Problems)​

  • Does not cover robots with very different sensing/actuation modalities.
  • Does not study generalization to new robots nor define a decision criterion for when positive transfer will occur.
  • Camera pose/properties and control frame remain unaligned; a deliberate but still challenging domain gap to address in future work.

Ref​

  • O’Neill, A., Rehman, A., Maddukuri, A., Gupta, A., Padalkar, A., Lee, A., Pooley, A., Gupta, A., Mandlekar, A., & Jain, A. (2024). Open x-embodiment: Robotic learning datasets and rt-x models: Open x-embodiment collaboration 0. 2024 IEEE International Conference on Robotics and Automation (ICRA).

FSD +006

· 약 4분

OOP vs Procedural Programming​

OOP​

  • a programming paradigm built around the concept of objects, which contain data and code to manipulate data.
  • The idea to model real-world entities and their interactions.
  • Global Data (fields) are enclosed in the objects.
  • Program components/tasks are easily divided across the development team / Requires more planning and design preparation
  • Easier to manage and maintain dependencies between objects / OOP programs are much larger and complex
  • Objects export the interface and hide the implementation and data / Tend to use more memory and GPU
  • Code is highly reusable and easy to scale and distribute / Making changes in one class potentially impact others, which can complicate the development of the code.

Procedural Programming​

  • the concept of procedure calls by structuring the program around procedures. (or functions/subroutines)
  • a sequential manner unless directed otherwise.
  • Global data (elements) is exposed to all the functions.
  • Easier to compile and interpret / Difficult to scale or extend
  • Straightforward and simpler to code / Dependencies between elements are unclear and not well-structured.
  • Less memory requirements / Data is exposed and insecure due to its exposure across the whole program
  • Easy to track the program flow / Hard to divide the work among programmers in a team.

Classes​

  • A class is a template/blueprint used to create objects
javapython
a pure OOP languagesupports OOP
code must be written in classesclasses are optional
executable class must have main()scripts run without including a class
Encapsulation can be enforced by declaring fields as privatefields (global variables) are public by default
Visibility is managed through access modifiersN/A ("_" to identify private data attributes, but still accessible)
class <class-name> (<extend - superclass>):
<variable-name> = <value> #Class fields - data members

def __init(self, <parameters>): #class constructor - object sbuilder
<code>

<method-name> (self, <parameters>): #methods
<code>

Classes Py​

KeywordsFunctions
class__init__()
self: keyword used to refer to object propertiesdel: the function is used to delete an object
pass: keyword used to occupy no-code placement in a function__str__(): The function is used to return string representation of instances
cls: keyword used to refer to class propertiessuper(): the function is used call a parent method in a child class
  • Accessors: functions (with no parameters) in a Python class that provide access to the data attributes of an object.
    • known as getter methods, are named starting with the verb get, followed by the field name, which should start with an uppercase letter.
  • Mutators: procedures (with parameter) in a Python class that enable the developer to modify the values of object attributes.
    • known as setter methods, are named starting with the verb set, followed by the field name, which should start with an uppercase letter.
def get<Variable> ():
return self.<field>

def set<Variable> (self, value):
self.<field> = value

Classes Java​

public class Bank {
private Customer customer;
private String branch;

public Bank() {
customer = new Customer();
}

public Bank(String name) {
this();
this.branch = name;
}

public boolean find(Bank bank) {
return this.branch.equals(bank.branch);
}
}

Packages​

Packages Java​

  • used to group related classes
  • like folders containing files (classes)
  • either Java defined or user-defined
  • used to write maintainable and portable code and to avoid class name conflicts.

Modules Py​

  • used to grou prelated functio nand classes together
  • normal Python scripts that are used into other scripts
  • either Python defined or user-defined
  • used to write maintainable and portable code to improve reusability

π0 Review

· 약 4분

π0​

Problem & Motivation​

  • Achieving real-world generality in robot learning is blocked by data scarcity, generalization, and robustness limits.
  • Human intelligence most outpaces machines in versatility—solving diverse, physically situated tasks under constraints, language commands, and perturbations.
  • In NLP/CV, foundation models pre-trained on diverse multi-task data, then fine-tuned (aligned) on curated datasets, outperform narrow specialists; the same paradigm is hypothesized for robotics.

Core Proposal​

  • A novel flow-matching architecture built on a pre-trained Vision-Language Model (VLM) to inherit Internet-scale semantics.
  • Further training adds robot actions, turning the model into a Vision-Language-Action (VLA) policy.
  • Use cross-embodiment training to combine data from many robot types (single/dual-arm, mobile), despite differing configuration/action spaces.
  • Employ action chunking + flow matching (diffusion variant) to model complex, continuous, high-frequency actions.
  • Introduce an Action Expert (separate weights for action/state tokens), akin to a Mixture-of-Experts, augmenting the standard VLM.

Training Recipe (Pre- vs Post-Training)​

  • Pre-training on highly diverse data builds broad, general physical abilities.
  • Post-training on curated, task-specific data instills fluent, efficient strategies.
  • Rationale: high-quality-only training lacks recovery behaviors; low-quality-only training lacks efficiency/robustness; combining both yields desired behavior.

Data & Backbone​

  • ~10,000 hours of demonstrations + the OXE dataset; data spans 7 robot configurations and 68 tasks.
  • VLM backbone initialized from PaliGemma (3B); add ~300M parameters for the action expert (total ~3.3B).
  • Pre-training mixture: weighted combination of internal datasets + full OXE; n^0.43 weighting to down-weight overrepresented task-robot pairs.
  • Unify interfaces: zero-pad qt/at to the largest robot dimension (18); mask missing image slots; late-fusion encoders map images/states to the same token space as language.

Modeling Details​

  • Conditional flow matching models the continuous distribution over action chunks.
  • Train with a diffusion-style loss on individual sequence elements (instead of cross-entropy), with separate weights for diffusion-related tokens.
  • Flow path uses a linear-Gaussian schedule; sample noisy actions with ε∼N(0, I); predict denoising vector field; Euler integration from τ=0→1 at inference.
  • Efficient inference by caching K/V for the observation prefix; action tokens recomputed per integration step.

High-Level Language Policy​

  • Because the policy consumes language, a high-level VLM can decompose tasks (e.g., bussing) into intermediate language subgoals (SayCan-style planning), improving performance on complex, temporally extended tasks.

Evaluation Setup & Baselines​

  • Out-of-box (direct prompting), fine-tuning on downstream tasks, and with high-level VLM providing intermediate commands.
  • Compare against OpenVLA (7B, autoregressive discretization; no action chunks/high-frequency control) and Octo (93M; diffusion), trained on the same mixture.
  • Include a compute-parity π0 (160k steps vs 700k) and a π0-small variant (no VLM init).

Key Results​

  • Out-of-box: π0 outperforms all baselines; even compute-parity π0 beats OpenVLA/Octo; π0-small still surpasses them—highlighting the benefits of expressive architectures + diffusion/flow matching + VLM pre-training.
  • Language following: π0 clearly exceeds π0-small across conditions:
    • π0-flat: only overall task command.
    • π0-human: human-provided intermediate steps.
    • π0-HL: high-level VLM-provided steps (fully autonomous).
    • Better language-following accuracy directly translates into stronger autonomous performance with high-level guidance.
  • New dexterous tasks (e.g., bowls stacking, towel folding, microwave, drawer items, paper towel replacement):
    • Fine-tuned π0 generally outperforms OpenVLA, Octo, and small-data methods ACT / Diffusion Policy.
    • Pre-training helps most when tasks resemble pre-training data; pretrained π0 often beats from-scratch by up to 2×.
  • Complex multi-stage tasks (laundry folding, table bussing, box building, to-go box, eggs):
    • π0 solves many tasks; full pre-training + fine-tuning performs best.
    • Gains from pre-training are especially large on harder tasks; absolute performance varies with task difficulty and pre-training coverage.

Takeaways & Limitations​

  • π0 mirrors LLM training: pre-train for knowledge, post-train for alignment (instruction-following and execution).
  • Limitations/open questions:
    • Optimal composition/weighting of pre-training data remains unclear.
    • Not all tasks work reliably; difficult to predict how much/what kind of data is needed for near-perfect performance.
    • Uncertain positive transfer across very diverse tasks/robots and to distinct domains (e.g., driving, navigation, legged locomotion).

Ref​

  • Black, K., Brown, N., Driess, D., Esmail, A., Equi, M., Finn, C., Fusai, N., Groom, L., Hausman, K., Ichter, B., Jakubczak, S., Jones, T., Ke, L., Levine, S., Li‑Bell, A., Mothukuri, M., Nair, S., Pertsch, K., Shi, L. X, … Zhilinsky, U. (2025, June 21). π₀: A vision‑language‑action flow model for general robot control Robotics: Science and Systems (RSS), Los Angeles, CA, United States. https://roboticsconference.org/program/papers/10/

Vima Review

· 약 2분

VIMA​

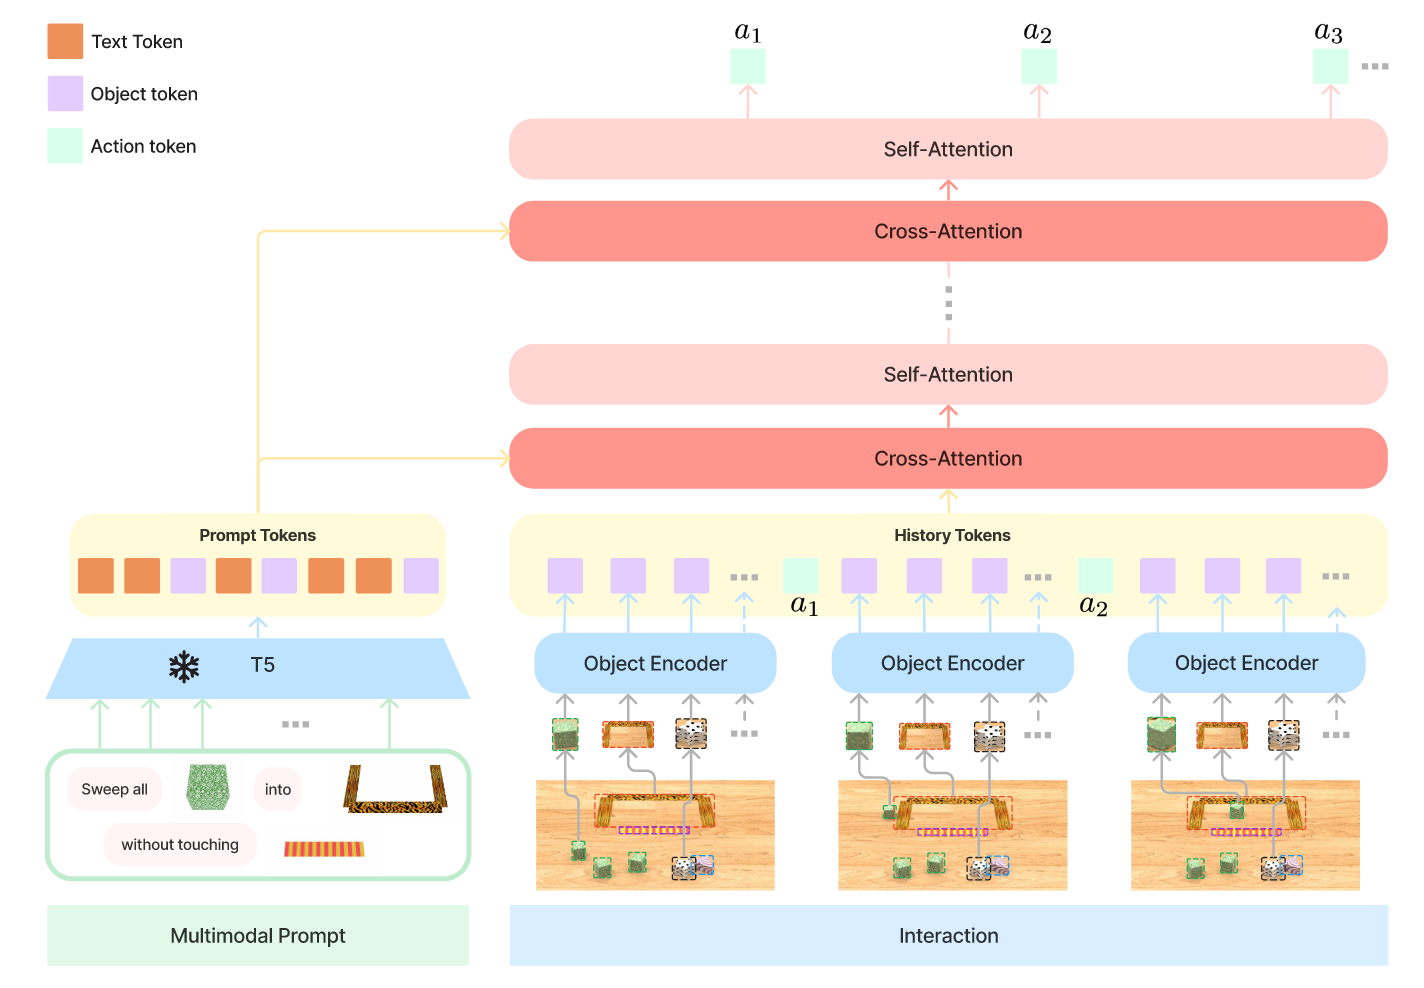
  • Unified Multimodal Prompts: Reformulates diverse robot tasks (language, images, video) into a single sequence modeling problem.
  • Object-Centric Tokenization: Uses object-level tokens (Mask R-CNN + ViT) instead of raw pixels, improving data efficiency and semantic generalization.
  • Cross-Attention Conditioning: Conditions the policy on prompts via cross-attention, maintaining strong zero-shot performance even with small models or novel tasks.

Motivation​

  • Robot task specification comes in many forms: one-shot demonstrations, language instructions, and visual goals.
  • Traditionally, each task required distinct architectures and pipelines, leading to siloed systems with poor generalization.

VIMA Architecture

Key Contributions​

  1. Multimodal Prompting

    • A novel formulation that unifies diverse robot manipulation tasks into a sequence modeling problem.
    • Prompts are defined as interleaved sequences of text and images, enabling flexibility across task formats.
  2. VIMA-BENCH

    • A large-scale benchmark with 17 tasks across six categories (object manipulation, goal reaching, novel concept grounding, video imitation, constraint satisfaction, visual reasoning).
    • Provides 650K expert trajectories and a four-level evaluation protocol for systematic generalization.
  3. VIMA Agent

    • A transformer-based visuomotor agent with encoder-decoder architecture and object-centric design.
    • Encodes prompts with a pre-trained T5 model, parses images into object tokens via Mask R-CNN + ViT, and decodes actions autoregressively using cross-attention.

Design Insights​

  • Object-Centric Representation: Passing variable-length object token sequences directly to the controller is more effective than pixel-based tokenization.
  • Cross-Attention Conditioning: Stronger prompt focus and efficiency compared to simple concatenation (e.g., GPT-style).
  • Robustness: Minimal degradation under distractors or corrupted prompts, aided by T5 backbone and object augmentation.

Results​

  • Performance:

    • Outperforms baselines (VIMA-Gato, VIMA-Flamingo, VIMA-GPT) by up to 2.9× success rate in hardest zero-shot generalization.
    • With 10× less training data, still 2.7× better than best competitor.
  • Scaling:

    • Sample-efficient: with just 1% of data, matches baselines trained with 10× more.
    • Generalization holds across L1–L4 evaluation, with smaller regression than alternatives.

Conclusion​

VIMA demonstrates that multimodal prompting is a powerful unifying framework for robot learning.
It achieves strong scalability, data efficiency, and generalization, establishing a solid starting point for future generalist robot agents.

Ref​

  • Jiang, Y., Gupta, A., Zhang, Z., Wang, G., Dou, Y., Chen, Y., Fei-Fei, L., Anandkumar, A., Zhu, Y., & Fan, L. (2023). VIMA: Robot Manipulation with Multimodal Prompts Proceedings of the 40th International Conference on Machine Learning, Proceedings of Machine Learning Research. https://proceedings.mlr.press/v202/jiang23b.html

RoboFlamingo Review

· 약 2분

RoboFlamingo​

  • RoboFlamingo decouples vision-language understanding and control, using OpenFlamingo for perception and a lightweight policy head for sequential decision-making.
  • Unlike prior VLM-based approaches, it requires only small-scale imitation fine-tuning on language-conditioned manipulation data, without large-scale co-fine-tuning.
  • This design enables data-efficient, zero-shot generalizable, and deployable robot manipulation policies on modest compute resources.

Key Idea​

  • Proposes RoboFlamingo, a simple framework to adapt existing VLMs for robotic manipulation with lightweight fine-tuning.
  • Built on OpenFlamingo, decoupling vision-language understanding from decision-making.
  • Pre-trained VLM handles language and visual comprehension, while a dedicated policy head models sequential history.
  • Fine-tuned only on language-conditioned manipulation datasets using imitation learning.

Advantages​

  • Requires only a small amount of demonstrations to adapt to downstream manipulation tasks.
  • Provides open-loop control capability → deployable on low-performance platforms.
  • Can be trained/evaluated on a single GPU server, making it a cost-effective and accessible solution.

Benchmarks​

  • Evaluated on CALVIN benchmark (34 tasks, 1000 instruction chains).
  • RoboFlamingo achieves 2× performance improvements over previous state-of-the-art methods.

Performance​

  • Imitation Learning: Outperforms all baselines across all metrics.
  • Zero-shot Generalization:
    • Vision: Stronger generalization in ABC→D setting.
    • Language: Robust to GPT-4 generated synonymous instructions.
  • Ablation Studies:
    • Ignoring history (MLP w/o hist) gives worst results.
    • LSTM and GPT-based policy heads perform best (LSTM chosen as default).
    • VL pre-training is crucial for downstream manipulation.
    • Larger VLMs show better data efficiency.
    • Instruction fine-tuning improves both seen and unseen tasks.

Flexibility of Deployment​

  • Supports open-loop control by predicting entire action sequences with a single inference → reduces latency and test-time compute.
  • Direct open-loop use without retraining can degrade performance; mitigated with jump-step demonstrations.

Conclusion​

  • Demonstrates that pre-trained VLMs enable data efficiency and strong zero-shot generalization in robotic manipulation.
  • RoboFlamingo is presented as an intuitive, efficient, and open solution, with high potential when combined with large-scale real robot data.

Ref​

  • Li, X., Liu, M., Zhang, H., Yu, C., Xu, J., Wu, H., Cheang, C., Jing, Y., Zhang, W., & Liu, H. (2024). Vision-language foundation models as effective robot imitators. International Conference on Learning Representations (ICLR 2024), Vienna, Austria.

OpenVLA Review

· 약 3분

OpenVLA​

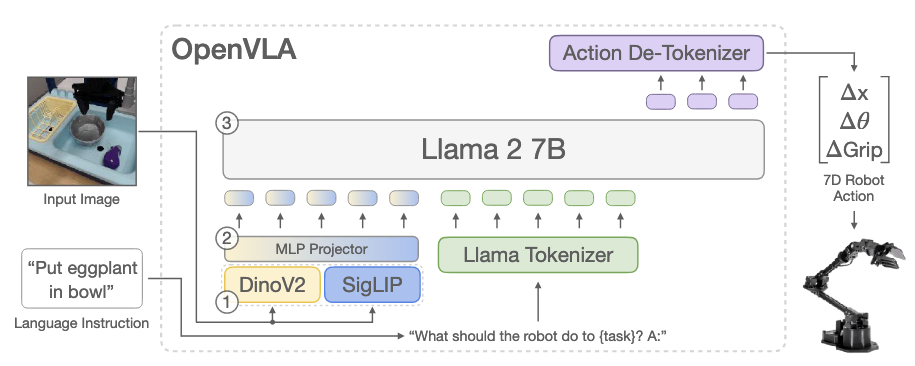
  • OpenVLA is a 7B open-source VLA model built on Llama2 + DINOv2 + SigLIP, trained on 970k demos, achieving stronger generalization and robustness than closed RT-2-X (55B) and outperforming Diffusion Policy.
  • It introduces efficient adaptation via LoRA (1.4% params, 8× compute reduction) and 4-bit quantization (half memory, same accuracy), enabling fine-tuning and inference on consumer GPUs.
  • Limitations remain (single-image input, <90% reliability, limited throughput), but OpenVLA provides the first open, scalable framework for generalist robot policies.

OpenVLA Architecture

Motivation​

  • Training robot policies from scratch struggles with robustness and generalization.
  • Fine-tuning vision-language-action (VLA) models offers reusable, generalizable visuomotor policies.
  • Barriers: prior VLAs are closed-source, lack best practices for adaptation, and need server-class hardware.

Model & Training​

  • OpenVLA: 7B parameters, open-source.
  • Built on Llama 2 with fused DINOv2 + SigLIP vision encoders.
  • Trained on 970k robot demonstrations from Open-X Embodiment dataset.
  • Represents robot actions as tokens (discretized into 256 bins, replacing unused Llama tokens).
  • Standard next-token prediction objective.

Architecture & Approach​

  • End-to-end fine-tuning of VLM to generate robot actions as tokens.
  • Differs from modular methods (e.g., Octo) that stitch separate encoders/decoders.
  • Vision features are obtained by encoding the same input image with both SigLIP and DINOv2, then channel-wise concatenated and passed through an MLP projector. This preserves SigLIP’s semantic alignment with language and DINOv2's spatial reasoning, giving the VLM richer multimodal context for manipulation tasks.
  • Uses Prismatic VLM backbone with multi-resolution features (spatial reasoning + semantics).

Performance​

  • Outperforms closed RT-2-X (55B) by +16.5% task success with 7× fewer parameters.
  • Beats Diffusion Policy (from-scratch imitation learning) by +20.4% on multi-task language-grounded settings.
  • Demonstrates robust behaviors (distractor resistance, error recovery).

Efficiency​

  • Introduces parameter-efficient fine-tuning:
    • LoRA updates only 1.4% of parameters yet matches full fine-tuning.
    • Can fine-tune on a single A100 GPU in ~10–15 hours (8× compute reduction).
  • Quantization:
    • 4-bit inference matches bfloat16 accuracy while halving memory footprint.
    • Runs at 3Hz on consumer GPUs (e.g., A5000, 16GB).

Evaluations​

  • Tested across 29 tasks and multiple robots (WidowX, Google robot, Franka).
  • Strong generalization on:
    • Visual (unseen backgrounds/distractors).
    • Motion (new object positions/orientations).
    • Physical (new object shapes/sizes).
    • Semantic (unseen tasks, instructions).
  • First generalist open-source VLA achieving ≥50% success rate across all tested tasks.

Design Insights​

  • Fine-tuning the vision encoder (vs. freezing) crucial for robotic control.
  • Higher image resolution (384px vs. 224px) adds 3× compute without performance gains.
  • Training required 27 epochs, far more than typical VLM runs, to surpass 95% action token accuracy.

Limitations & Future Work​

  • Supports only single-image observations (no proprioception, no history).
  • Inference throughput (~6Hz on RTX 4090) insufficient for high-frequency control (e.g., ALOHA at 50Hz).
  • Success rates remain below 90% in challenging tasks.
  • Open questions:
    • Impact of base VLM size on performance.
    • Benefits of co-training with Internet-scale data.
    • Best visual features for VLAs.

Contributions​

  1. First open-source generalist VLA with strong performance.
  2. Scalable end-to-end training pipeline (action-as-token).
  3. Demonstrates LoRA + quantization for consumer-grade GPU adaptation.
  4. Provides code, checkpoints, and data curation recipes to support future research.

Ref​

  • Kim, M. J., Pertsch, K., Karamcheti, S., Xiao, T., Balakrishna, A., Nair, S., Rafailov, R., Foster, E. P., Sanketi, P. R., Vuong, Q., Kollar, T., Burchfiel, B., Tedrake, R., Sadigh, D., Levine, S., Liang, P., & Finn, C. (2025). OpenVLA: An Open-Source Vision-Language-Action Model Proceedings of The 8th Conference on Robot Learning, Proceedings of Machine Learning Research. https://proceedings.mlr.press/v270/kim25c.html

데이터 시각화 의사 결정 트리

· 약 3분

Color Legend​

IconCategoryDescriptionExample
🟡Distribution분포를 보여주고 싶을 때Histogram, Density plot
⚫Correlation상관관계를 보여주고 싶을 때Scatterplot, Correlogram
🟢Ranking순위를 보여주고 싶을 때Bar chart, Lollipop chart
🔴Part of a whole전체 중 일부를 보여주고 싶을 때Pie chart, Treemap
🔵Evolution시간에 따른 변화를 보여주고 싶을 때Line chart, Area chart
🟣Maps지도를 활용해서 공간적 정보를 보여줄 때Choropleth map, Bubble Map
🟤Flow흐름(흐름도, 이동 경로 등)을 보여줄 때Flow map, Sankey-like

Categoric​

  • One Variable
    • ⚫ Waffle
    • 🟢 Bar Plot
    • 🟢 Lollipop
    • 🟢 Word Cloud
    • 🔴 Circular Packing
    • 🔴 Doughnut
    • 🔴 Pie
    • 🔴 Treemap
  • Two or More Variables
    • Two Independent Lists
      • 🔴 Venn Diagram
    • Nested
      • 🟢 Bar Plot
      • 🔴 Circular Packing
      • 🔴 Dendrogram
      • 🔴 Sunburst
      • 🔴 Treemap
    • Subgroup
      • ⚫ Grouped Scatter
      • ⚫ Heatmap
      • 🟢 Lollipop
      • 🟢 Parallel Plot
      • Spider
      • 🔴 Grouped Bar Plot
      • 🔴 Grouped Bar Plot
      • 🟤 Sankey Diagram
    • Adjacency
      • 🟤 Arc
      • 🟤 Chord
      • 🟤 Network
      • 🟤 Sankey
      • ⚫ Heatmap

Relational​

  • Network
    • ⚫ Heatmap
    • 🟢 Hive
    • 🟤 Arc
    • 🟤 Chord
    • 🟤 Network
    • 🟤 Sankey
  • Nested
    • No Value
      • 🔴 Circular Packing
      • 🔴 Dendrogram
      • 🔴 Sunburst
      • 🔴 Treemap
      • 🟤 Sankey
    • Value for Leaf
      • 🔴 Circular Packing
      • 🔴 Dendrogram
      • 🔴 Sunburst
      • 🔴 Treemap
      • 🟤 Sankey
    • Value for Edges
      • 🔴 Dendrogram
      • 🟤 Chord
      • 🟤 Sankey
    • Value for Connection
      • Edge Bundling

Map​

  • 🟣 Bubble Map
  • 🟣 Choropleth
  • 🟣 Connected Map
  • 🟣 Map
  • 🟣 Map Hexbin

Time Series​

  • One Series
    • 🟡 Box Plot
    • 🟡 Violin
    • 🟡 Ridge Line
    • 🔵 Area
    • 🔵 Line Plot
    • 🟢 Bar Plot
    • 🟢 Lollipop
  • Several Series
    • 🟡 Box Plot
    • 🟡 Violin
    • 🟡 Ridge Line
    • ⚫ Heatmap
    • 🔵 Line Plot
    • 🔵 Stacked Area
    • 🔵 Stream Graph

Categoric and Numeric​

  • One Numeric + One Categoric
    • One Observation, per Group
      • ⚫ Waffle
      • 🟢 Bar Plot
      • 🟢 Lollipop
      • 🟢 Word Cloud
      • 🔴 Circular Packing
      • 🔴 Doughnut
      • 🔴 Pie
      • 🔴 Treemap
    • Several Observations, per Group
      • 🟡 Box Plot
      • 🟡 Violin
      • 🟡 Ridge Line
      • 🟡 Density
      • 🟡 Histogram
  • One Category, Several Numeric
    • No Order
      • 🟡 Box Plot
      • 🟡 Violin
      • ⚫ Grouped Scatter
      • ⚫ 2D Density
      • ⚫ PCA
      • ⚫ Correlogram
    • A Numeric is Ordered
      • ⚫ Connected Scatter
      • 🔵 Area
      • 🔵 Line Plot
      • 🔵 Stacked Area
      • 🔵 Stream Graph
    • One Value Per Group
      • ⚫ Grouped Scatter
      • ⚫ Heatmap
      • 🟢 Lollipop
      • 🟢 Parallel Plot
      • 🟢 Spider Plot
      • 🔴 Grouped Bar Plot
      • 🔴 Grouped Bar Plot
      • 🟤 Sankey Diagram
  • Several Categories, One Numeric
    • Subgroup
      • One Observation. per Group
        • ⚫ Grouped Scatter
        • ⚫ Heatmap
        • 🟢 Lollipop
        • 🟢 Parallel Plot
        • 🟢 Spider Plot
        • 🔴 Grouped Bar Plot
        • 🔴 Grouped Bar Plot
        • 🟤 Sankey Diagram
      • Several Observations, per Group
        • 🟡 Box Plot
        • 🟡 Violin
    • Nested
      • One Observation. per Group
        • 🟢 Bar Plot
        • 🔴 Circular Packing
        • 🔴 Dendrogram
        • 🔴 Sunburst
        • 🔴 Treemap
      • Several Observations. per Group
        • 🟡 Box Plot
        • 🟡 Violin
    • Adjacency
      • ⚫ Heatmap
      • 🟤 Arc
      • 🟤 Chord
      • 🟤 Network
      • 🟤 Sankey

Numeric​

  • One Numeric Variable
    • 🟡 Density
    • 🟡 Histogram
  • Two Numeric Variables
    • Not Ordered
      • Few Points
        • 🟡 Box Plot
        • 🟡 Histogram
        • ⚫ Scatter Plot
      • Many Points
        • 🟡 Density
        • 🟡 Violin
        • ⚫ 2D Density
        • 🔵 Marginal Distribution
    • Ordered
      • ⚫ Connected Scatter
      • 🔵 Area Plot
      • 🔵 Line Plot
  • Three Numeric Variables
    • Not Ordered
      • 🟡 Box Plot
      • 🟡 Violin
      • ⚫ Bubble Plot
      • ⚫ 3d Scatter or Surface
    • Ordered
      • 🔵 Area
      • 🔵 Line Plot
      • 🔵 Stacked Area
      • 🔵 Stream Graph
  • Several Numeric Variables
    • Ordered
      • 🔵 Area
      • 🔵 Line Plot
      • 🔵 Stacked Area
      • 🔵 Stream Graph
    • Not Ordered
      • 🟡 Box Plot
      • 🟡 Ridge Line
      • 🟡 Violin
      • ⚫ Correlogram
      • ⚫ Heatmap
      • ⚫ PCA
      • 🔴 Dendrogram

Ref​

Vocabulary for AI +006

· 약 2분

Vocabulary & Expressions​

Term/ExpressionDefinitionSimpler ParaphraseMeaning
prevalenceThe state of being widespread or commonCommonness유행, 널리 퍼짐
instantiationThe act of creating a specific instance of somethingCreation of a specific example구체적인 값의 생성
trivialityThe quality of being trivial or unimportantUnimportance사소함, 하찮음
intermediaryA person or thing that acts as a link between two othersMiddleman중개자, 매개체
dreadedRegarded with great fear or apprehensionFeared두려운, 걱정되는
i.i.d.Independent and identically distributedSame distribution, no dependence독립적이고 동일한 분포
posterioriRelating to knowledge gained through experience or empirical evidenceBased on observation경험적, 관찰에 기초한
posteriorRelating to the back or rearBack뒤쪽의, 후방의
resemblanceThe state of resembling or being alikeSimilarity유사성, 닮음
stipulateTo demand or specify a requirementSpecify규정하다, 명시하다
rectifyTo correct or make rightCorrect수정하다, 바로잡다
schematicRelating to a diagram or representationDiagrammatic도식적인, 다이어그램의
propositionA statement or assertion that expresses a judgment or opinionProposal제안, 명제
cavityA cavity is a hollow place in a tooth caused by decayTooth decay충치
tautologicalRelating to or involving tautology (the saying of the same thing twice in different words)Redundant동의어 반복의, 중복적인
retrospectivelyLooking back on or dealing with past events or situationsLooking back회고적으로, 과거를 돌아보며
perturbationsDisturbances or deviations from a normal stateDisturbances교란, 변동
deformableCapable of being changed in shape or formChangeable변형 가능한
ConsolidationThe process of combining multiple elements into a single, more effective wholeIntegration통합
oscillationFluctuation or variation in a state or conditionFluctuation진동, 변동
homogeneousOf the same kind; alikeUniform동질의, 균일한
nonstationaryNot stationary; changing over timeChanging비정상적인, 시간에 따라 변하는
whereuponImmediately after whichAfter which그 후에, 그 다음에
magnitudeThe great size or extent of somethingSize크기, 규모
maneuverA movement or series of moves requiring skill and careMove조작, 움직임

Developing ML Systems

· 약 5분

Problem formulation (문제 정의)​

  • The first step is to figure out what problem you want to solve.
    1. “사용자에게 어떤 문제를 해결해주고 싶은가?” → 모호하지 않고 구체적으로 정의해야 함.
    2. “그 문제 중 어떤 부분을 머신러닝으로 풀 수 있는가?” → 예: 사진을 라벨로 매핑하는 함수 학습.
  • 이를 구체화하려면 ML 컴포넌트에 대해 loss function 을 지정해야 한다.
  • 문제를 쪼개보면 일부는 전통적 SW 엔지니어링으로 해결 가능하고, 일부만 ML로 다뤄야 할 수 있다.
  • 학습 유형은 지도·비지도·강화·준지도(semisupervised)까지 연속선상에 있음.
    • Semisupervised learning: 일부 라벨만 활용해 비라벨 데이터에서 더 많은 정보 추출.
    • Weakly supervised learning: 부정확·노이즈 라벨을 사용.
  • 결론: Noise와 label 부족은 “지도 ↔ 비지도” 사이의 연속체를 형성한다.

Data collection & management (데이터 수집/관리)​

  • 데이터는 직접 제작, 크라우드소싱, 사용자 행동에서 수집 가능.
  • 부족할 때는 transfer learning 활용.
  • Privacy 검토와 동의, 공정성, federated learning 등 고려 필요.
  • Data provenance(출처 관리): 데이터 정의, 값의 범위, 생성 주체, 중단 여부, 정의 변경 이력 등 추적 → 파이프라인 안정성이 알고리즘보다 중요.
  • 항상 자문: “이 데이터는 내 문제를 풀기에 적절한가? 입력과 출력 모두 충분히 담고 있는가?”
  • Learning curve 로 데이터 확장 효과/학습 plateau 확인.
  • 방어적 태도 필요: 입력 오류, 누락, 적대적 사용자, 철자 불일치 등 처리.
  • Data augmentation (회전, 이동, 노이즈 추가 등)으로 모델 강건성 향상.
  • 불균형 데이터는 undersampling, oversampling, SMOTE/ADASYN, boosting 등으로 완화.
  • 아웃라이어는 로그 변환 등으로 영향 축소, 트리 모델은 상대적으로 강건.

Feature engineering (특징 엔지니어링)​

  • Quantization: 연속값을 구간(bin)으로 강제.
  • One-hot encoding: 범주형 속성을 다중 Boolean으로 변환.
  • 도메인 지식 기반 새 특성 추가 (예: 날짜 → 주말/공휴일 여부).
  • “At the end of the day, some ML projects succeed and some fail… the most important factor is the features used.” (Pedro Domingos)

Exploratory data analysis (EDA) & visualization​

  • 목표: 예측/검증이 아닌 데이터 이해.
  • Histograms, scatter plots 로 분포/결측/오류/이상치 확인.
  • 클러스터링 → 프로토타입 시각화, 이상치 탐지 (“고양이 vs 사자 옷 입은 고양이”).
  • 차원 축소 (예: t-SNE)로 고차 데이터를 2D/3D로 시각화.

Model selection & training​

  • 데이터가 정리되면 모델 구축 단계.
  • Random forests → 범주형 특징 많고 일부 무관할 때.
  • Nonparametric methods → 데이터 많고 지식 부족, 특징 선택 고민 줄이고 싶을 때.
  • Logistic regression → 선형 분리 가능(또는 feature engineering 후).
  • SVM → 데이터 크기 작고 차원 높을 때.
  • Deep neural nets → 패턴 인식(이미지·음성).
  • 하이퍼파라미터는 경험 + 탐색으로 조율.
  • 검증 데이터 남용 시 validation overfitting 위험 → 여러 검증셋 필요.
  • 성능 평가: ROC curve, AUC, confusion matrix.
  • 중요한 건 아이디어–실험–검증 반복 사이클을 빠르게 하는 것.

Trust, interpretability, explainability​

  • 단순히 지표 성능만으로는 신뢰 부족 → 규제·언론·사용자도 신뢰성 원함.
  • Accountability: 오류 발생 시 책임 주체와 항소 절차 필요.
  • Interpretability: 모델 내부를 직접 이해 (트리, 선형회귀).
    • 핵심 질문: “If I change x, how will the output change?”
  • Explainability: 블랙박스 모델 + 별도 모듈로 설명 (예: LIME).
  • 단순 설명이 잘못된 확신을 줄 수 있음. → 테스트와 실제 성능이 더 큰 신뢰를 준다.
  • “안전하다고 설명만 있는 실험기 vs 100회 무사비행한 비행기” 비유.

Operation, monitoring, maintenance​

  • 운영 단계에서는 롱테일 입력(long tail) 문제 등장 → 예상 못한 입력 지속 발생. → 실시간 모니터링과 사람 평가자 필요.
  • Nonstationarity: 세상과 사용자 행동 변화 → 최신 데이터 vs 안정적 모델 트레이드오프.
  • 신선도 요구 다름: 어떤 문제는 매일/매시간 새 모델, 어떤 문제는 수개월 동일 모델.
  • 배포 자동화 → 작은 변경은 자동 승인, 큰 변경은 리뷰.
  • Online vs Offline model: 기존 모델 점진적 수정 vs 매번 처음부터 재학습.
  • 데이터 자체가 바뀔 수도 있음 (스팸 이메일 → 스팸 문자, 음성, 영상 등).

Checklist​

Tests for Features and Data​

  • Feature expectations are captured in a schema.
  • All features are beneficial.
  • No feature’s cost is too much.
  • Features adhere to meta-level requirements.
  • The data pipeline has appropriate privacy controls.
  • New features can be added quickly.
  • All input feature code is tested.

Tests for Model Development​

  • Every model specification undergoes a code review.
  • Every model is checked in to a repository.
  • Offline proxy metrics correlate with actual metrics.
  • All hyperparameters have been tuned.
  • The impact of model staleness is known.
  • A simpler model is not better.
  • Model quality is sufficient on all important data slices.
  • The model has been tested for considerations of inclusion.

Tests for Machine Learning Infrastructure​

  • Training is reproducible.
  • Model specification code is unit tested.
  • The full ML pipeline is integration tested.
  • Model quality is validated before attempting to serve it.
  • The model allows debugging by observing the step-by-step computation of training or inference on a single example.
  • Models are tested via a canary process before they enter production serving environments.
  • Models can be quickly and safely rolled back to a previous serving version.

Monitoring Tests for Machine Learning​

  • Dependency changes result in notification.
  • Data invariants hold in training and serving inputs.
  • Training and serving features compute the same values.
  • Models are not too stale.
  • The model is numerically stable.
  • The model has not experienced regressions in training speed, serving latency, throughput, or RAM usage.
  • The model has not experienced a regression in prediction quality on served data.

Ref​

  • Breck, E., Cai, S., Nielsen, E., Salib, M., & Sculley, D. (2016). What’s your ML test score? A rubric for ML production systems. NIPS Workshop on Reliable Machine Learning in the Wild.