Temporal-Difference Learning
Updates a guess towards a guess.
Model-free : No MDP Dynamics or RewardsLearns directly from episodes of experience.
Bootstrapping : Estimate value function using estimated value from incomplete episodes.
Update estimate using another estimate.
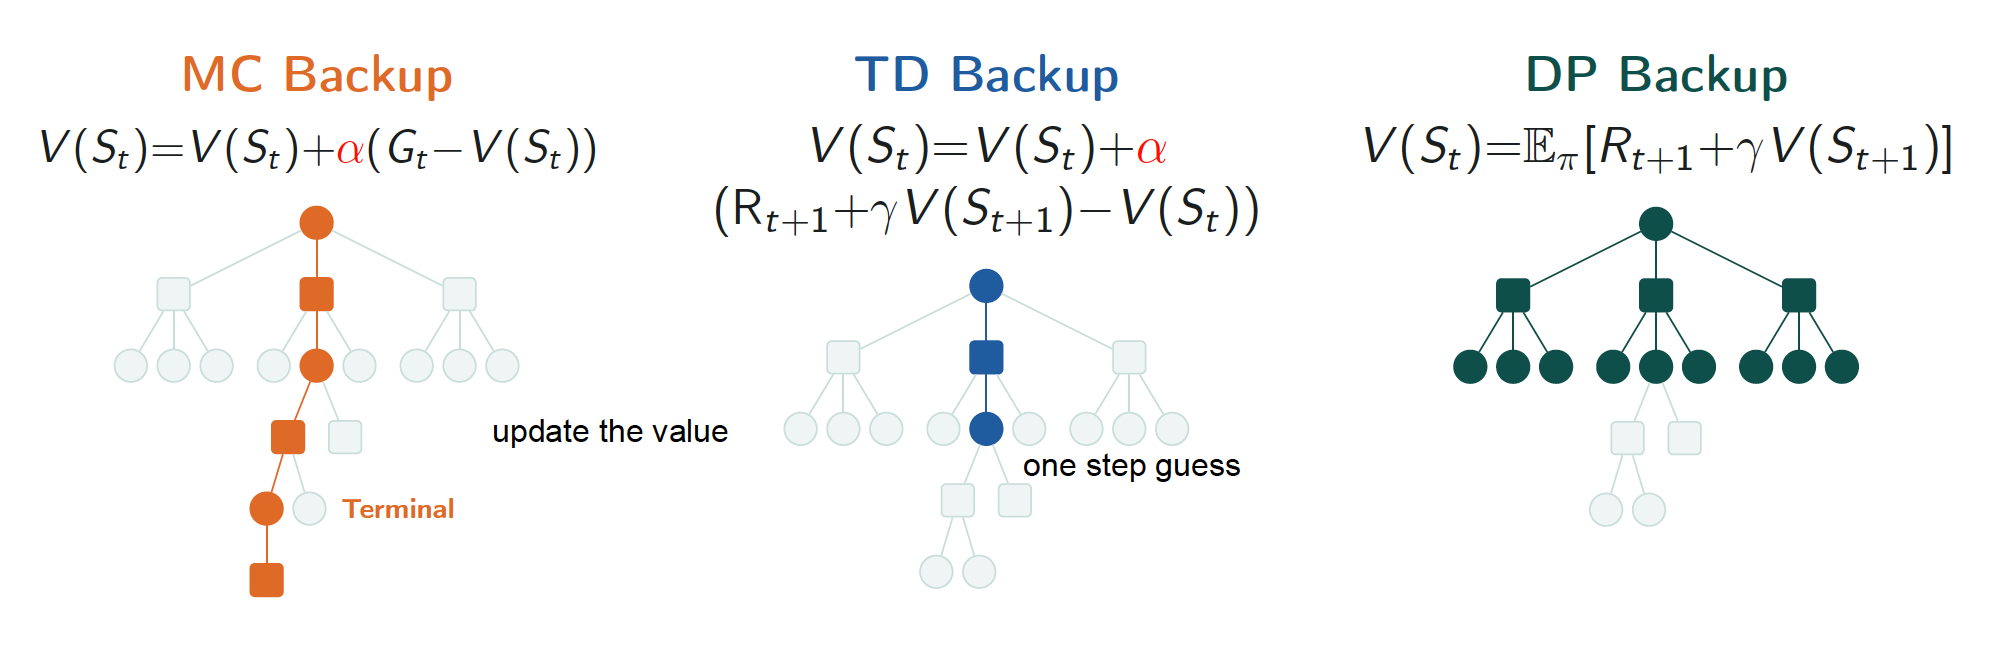
Updates the estimate of V V V Combines Monte Carlo and Dynamic Programming (Bootstrapping idea).
V ( S t ) = V ( S t ) + α [ G t ⏟ Goal − V ( S t ) ⏟ Previous estimate ] V(S_t) = V(S_t) + \alpha [\underbrace{G_t}_{\text{Goal}} - \underbrace{V(S_t)}_{\text{Previous estimate}} ] V ( S t ) = V ( S t ) + α [ Goal G t − Previous estimate V ( S t ) ]
Update V ( S t ) V(S_t) V ( S t )
α = 1 n \alpha = \frac{1}{n} α = n 1
gives equal weight to all past samples in the arithmetic mean .
Fixed α > 1 n \alpha > \frac{1}{n} α > n 1
α = 0.1 , V ( S ) = 10 \alpha = 0.1, \quad V(S) = 10 α = 0.1 , V ( S ) = 10 V ( S ) ← 10 + 0.1 ( 20 − 10 ) = 11 V(S) \leftarrow 10 + 0.1 (20 - 10) = 11 V ( S ) ← 10 + 0.1 ( 20 − 10 ) = 11 V ( S ) ← 11 + 0.1 ( 30 − 11 ) = 12.9 V(S) \leftarrow 11 + 0.1 (30 - 11) = 12.9 V ( S ) ← 11 + 0.1 ( 30 − 11 ) = 12.9 Move 10% of the way towards the new value.
One-Step Bootstrapping
TD ( 0 ) → TD ( λ ) → TD ( 1 ) ≈ MC \text{TD}(0) \rightarrow \text{TD}(\lambda) \rightarrow \text{TD}(1) \approx \text{MC} TD ( 0 ) → TD ( λ ) → TD ( 1 ) ≈ MC
λ \lambda λ
It controls how far into the future TD learns from.
λ = 0 \lambda = 0 λ = 0 As λ \lambda λ
λ = 1 \lambda = 1 λ = 1 Monte Carlo return in episodic tasks.
V ( S t ) = V ( S t ) + α [ R t + 1 + γ V ( S t + 1 ) ⏟ TD target − V ( S t ) ⏟ TD Error ] V(S_t) = V(S_t) + \alpha [\underbrace{\underbrace{R_{t+1} + \gamma V(S_{t+1})}_{\text{TD target}} - V(S_t)}_{\text{TD Error}} ] V ( S t ) = V ( S t ) + α [ TD Error TD target R t + 1 + γV ( S t + 1 ) − V ( S t ) ]
Only one immediate reward is used R t + 1 R_{t+1} R t + 1
Everything after that is replaced by the current guess V ( S t + 1 ) V(S_{t+1}) V ( S t + 1 )
It uses actual reward for the first step and the estimated value/guess for the rest.
MC
Sₜ ──Rₜ₊₁──> Sₜ₊₁ ──Rₜ₊₂──> ... ──> Terminal
│                                        │
└────────── episode 끝까지 기다림 ────────┘
                   ↓
               actual Gₜ
                   ↓
              V(Sₜ) update


TD(0)
Sₜ ──Rₜ₊₁──> Sₜ₊₁ ── ? ──> ...
│              │
│              └─ current V(Sₜ₊₁)
│
└── Rₜ₊₁ + γV(Sₜ₊₁)로 즉시 V(Sₜ) update
TD(0) Algorithm
Loop for each episode: Initialize S Loop for each step of the episode: A ← action given by policy π Take action A , observe R , S ′ V ( S ) ← V ( S ) + α [ R + γ V ( S ′ ) − V ( S ) ] S ← S ′ Until S is terminal \begin{aligned}
&\text{Loop for each episode:} \\
&\quad \text{Initialize} \quad S \\
&\quad \text{Loop for each step of the episode:} \\
&\quad \quad A \leftarrow \text{action given by policy} \quad \pi \\
&\quad \quad \text{Take action} \quad A, \quad \text{observe} \quad R, \quad S' \\
&\quad \quad V(S) \leftarrow V(S) + \alpha [R + \gamma V(S') - V(S)] \\
&\quad \quad S \leftarrow S' \\
&\quad \text{Until} \quad S \text{ is terminal} \\
\end{aligned} Loop for each episode: Initialize S Loop for each step of the episode: A ← action given by policy π Take action A , observe R , S ′ V ( S ) ← V ( S ) + α [ R + γV ( S ′ ) − V ( S )] S ← S ′ Until S is terminal
No need to wait until the end of the episode to update the value function.
MC vs. TD
Aspect Monte Carlo (MC) Temporal-Difference (TD) Learning sequence Learns from complete episodes Learns from incomplete episodes Target Actual return G t G_t G t Estimated return using bootstrapping Update timing After the episode ends Before the episode ends / step by step Future information Uses actual future rewards Uses observed reward(s) + estimated future value Bootstrapping No Yes Bias Unbiased Biased Variance High Low Environment Episodic / terminating environments Also works in continuing / non-terminating environments Practical speed Slower updates Faster updates in practice
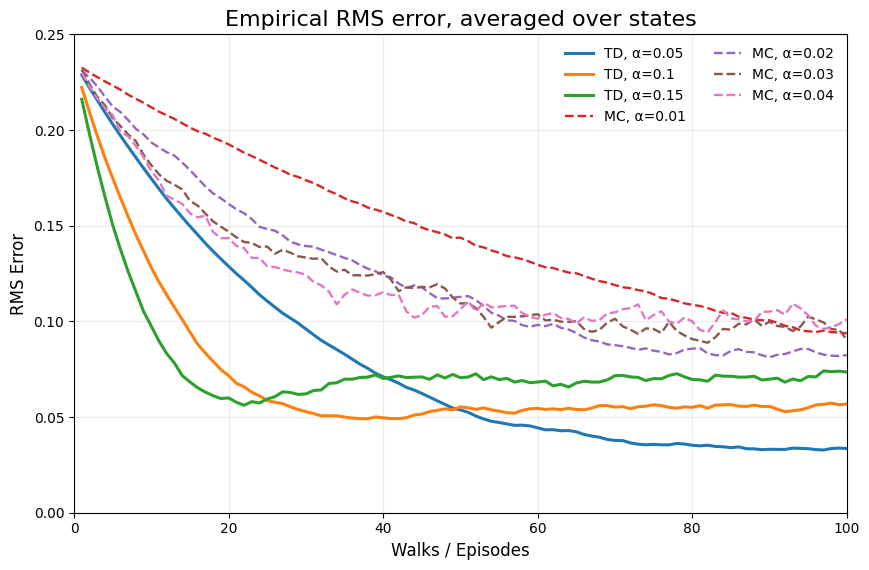
In practice, TD is faster than MC because it can learn from incomplete episodes.
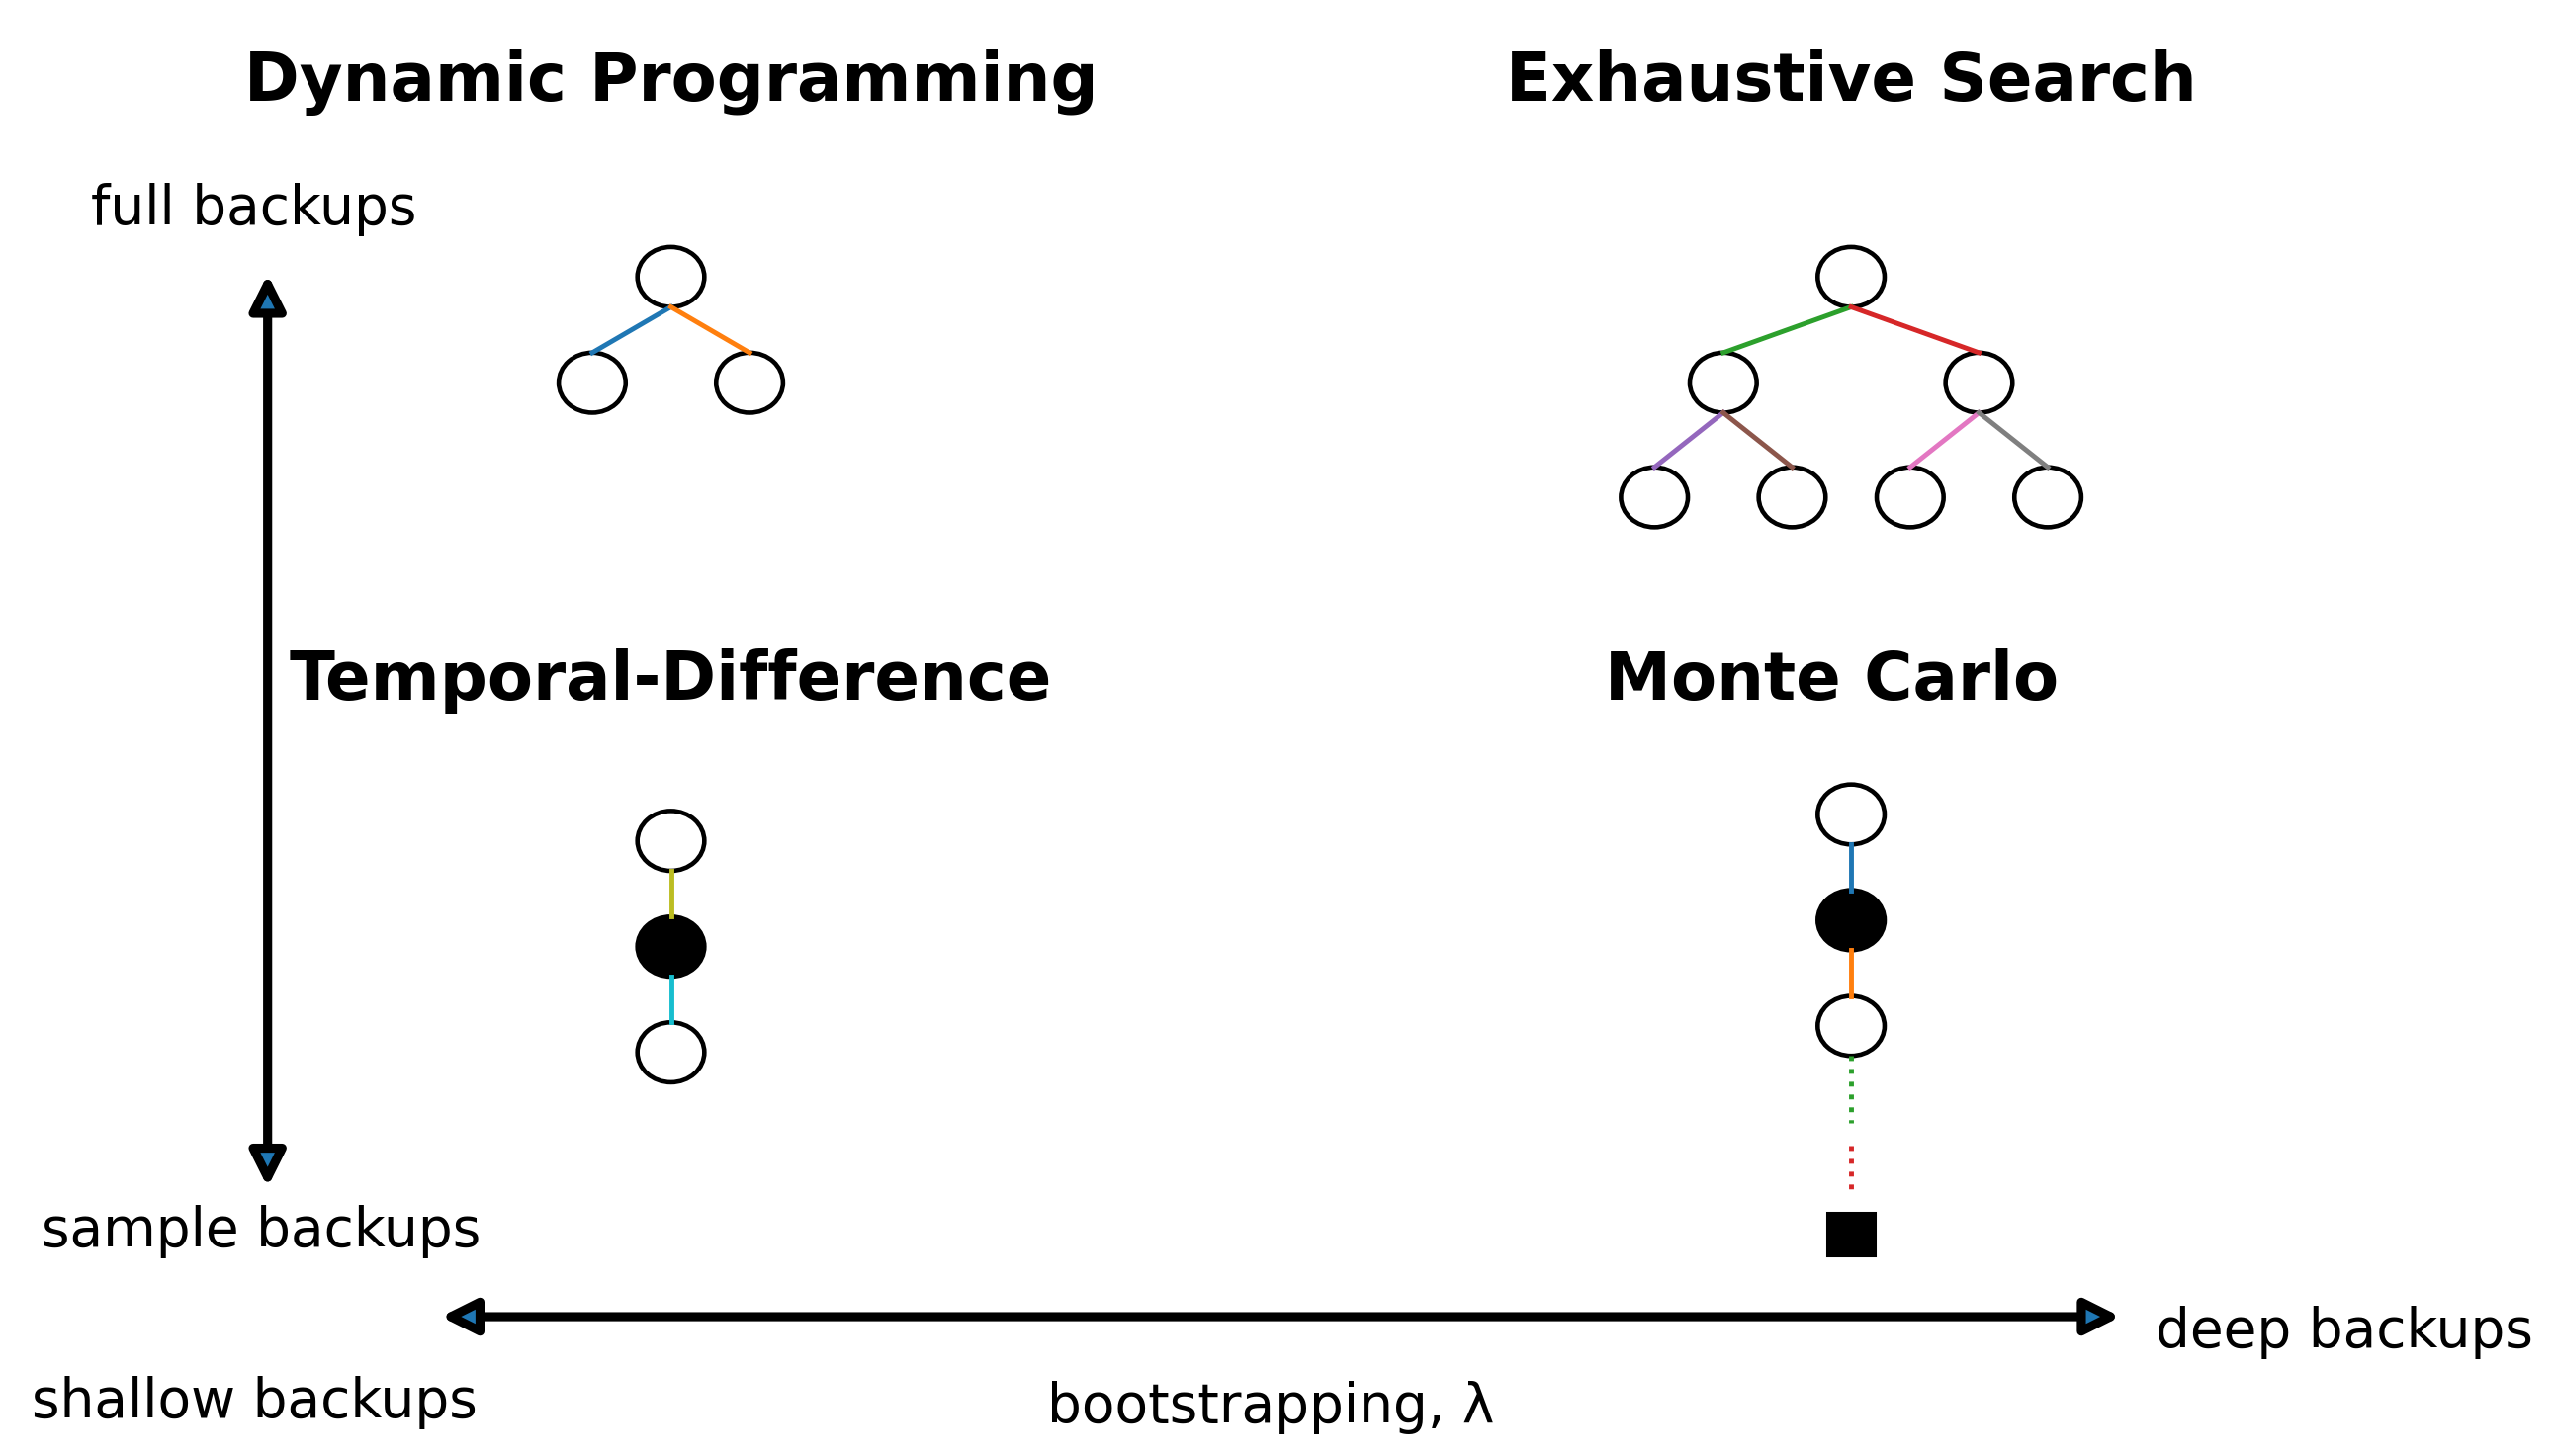
MC: Full sampled path to the end.
TD: Just one real step.
DP: Every branch, weighted by probability, no sampling.
SARSA
S t , A t , R t + 1 , S t + 1 , A t + 1 S_t, A_t, R_{t+1}, S_{t+1}, A_{t+1} S t , A t , R t + 1 , S t + 1 , A t + 1
Follows generalized Policy Iteration.
Policy Evaluation: TD Policy Evaluation Q ≈ q π Q \approx q_\pi Q ≈ q π
Policy Improvement: ϵ \epsilon ϵ
Update happens after every time step.
Use TD methods for evaluation. Q ( S , A ) Q(S, A) Q ( S , A )
TD Evaluation + ϵ \epsilon ϵ SARSA
Q ( S t , A t ) = Q ( S t , A t ) + α [ R t + 1 + γ Q ( S t + 1 , A t + 1 ) ⏟ TD target − Q ( S t , A t ) ] Q(S_t, A_t) = Q(S_t, A_t) + \alpha [\underbrace{R_{t+1} + \gamma Q(S_{t+1}, A_{t+1})}_{\text{TD target}} - Q(S_t, A_t)] Q ( S t , A t ) = Q ( S t , A t ) + α [ TD target R t + 1 + γ Q ( S t + 1 , A t + 1 ) − Q ( S t , A t )]
( S t , A t , R t + 1 , S t + 1 , A t + 1 ) (S_t, A_t, R_{t+1}, S_{t+1}, A_{t+1}) ( S t , A t , R t + 1 , S t + 1 , A t + 1 ) The process repeatedly alternates between improving Q Q Q
The estimates gradually move toward the optimal action-value function q ∗ q_* q ∗ π ∗ \pi_* π ∗
Unlike classical policy iteration, SARSA does not need to complete policy evaluation before improving the policy.
SARSA Example
Q ( S t , A t ) = 10 Q(S_t,A_t)=10 Q ( S t , A t ) = 10 R t + 1 = 2 R_{t+1}=2 R t + 1 = 2 γ = 0.9 \gamma=0.9 γ = 0.9 α = 0.5 \alpha=0.5 α = 0.5 Q ( S t + 1 , A t + 1 ) = 8 Q(S_{t+1},A_{t+1})=8 Q ( S t + 1 , A t + 1 ) = 8 TD Target = 2 + 0.9 ( 8 ) = 9.2 =2+0.9(8)=9.2 = 2 + 0.9 ( 8 ) = 9.2
TD Error = 9.2 − 10 = − 0.8 =9.2-10=-0.8 = 9.2 − 10 = − 0.8
Updated Q ( S t , A t ) = 10 + 0.5 ( − 0.8 ) = 9.6 Q(S_t,A_t)=10+0.5(-0.8)=9.6 Q ( S t , A t ) = 10 + 0.5 ( − 0.8 ) = 9.6
SARSA Algorithm
Loop for each episode: Initialize S Choose A t from S t using policy π derived from Q Loop for each step of the episode: Take action A t + 1 , observe R t + 1 , S t + 1 Q ( S t , A t ) ← Q ( S t , A t ) + α [ R t + 1 + γ Q ( S t + 1 , A t + 1 ) − Q ( S t , A t ) ] S t ← S t + 1 A t ← A t + 1 Until S is terminal \begin{aligned}
&\text{Loop for each episode:} \\
&\quad \text{Initialize} \quad S \\
&\quad \text{Choose} A_t \text{ from } S_t \text{ using policy } \pi \text{ derived from } Q\\
&\quad \text{Loop for each step of the episode:} \\
&\quad \quad \text{Take action} \quad A_{t+1}, \quad \text{observe} \quad R_{t+1}, \quad S_{t+1} \\
&\quad \quad Q(S_t, A_t) \leftarrow Q(S_t, A_t) + \alpha [R_{t+1} + \gamma Q(S_{t+1}, A_{t+1}) - Q(S_t, A_t)] \\
&\quad \quad S_t \leftarrow S_{t+1} \\
&\quad \quad A_t \leftarrow A_{t+1} \\
&\quad \text{Until} \quad S \text{ is terminal} \\
\end{aligned} Loop for each episode: Initialize S Choose A t from S t using policy π derived from Q Loop for each step of the episode: Take action A t + 1 , observe R t + 1 , S t + 1 Q ( S t , A t ) ← Q ( S t , A t ) + α [ R t + 1 + γ Q ( S t + 1 , A t + 1 ) − Q ( S t , A t )] S t ← S t + 1 A t ← A t + 1 Until S is terminal
As SARSA learns, each episode is completed faster.
As the Q-values improve, the agent learns better actions for each state and reaches the goal using fewer steps.
Q-Learning
On-policy: SARSA, behavior policy is the same as the target policy.
Off-policy: Q-Learning, behavior policy is different from the target policy. Q ( S , A ) Q(S, A) Q ( S , A )
Update Q ( S t , A t ) Q(S_t, A_t) Q ( S t , A t )
Q ( S t , A t ) = Q ( S t , A t ) + α [ R t + 1 + γ max a Q ( S t + 1 , a ) ⏟ TD target − Q ( S t , A t ) ] Q(S_t, A_t) = Q(S_t, A_t) + \alpha [\underbrace{R_{t+1} + \gamma \max_{a} Q(S_{t+1}, a)}_{\text{TD target}} - Q(S_t, A_t)] Q ( S t , A t ) = Q ( S t , A t ) + α [ TD target R t + 1 + γ a max Q ( S t + 1 , a ) − Q ( S t , A t )]
The Actual next action is replaced by the Best possible action.
Q ( S t , A t ) = 10 Q(S_t, A_t)=10 Q ( S t , A t ) = 10 R t + 1 = 2 R_{t+1}=2 R t + 1 = 2 γ = 0.9 \gamma=0.9 γ = 0.9 α = 0.5 \alpha=0.5 α = 0.5 Q ( S t + 1 , a 1 ) = 8 Q(S_{t+1}, a_1)=8 Q ( S t + 1 , a 1 ) = 8 Q ( S t + 1 , a 2 ) = 11 Q(S_{t+1}, a_2)=11 Q ( S t + 1 , a 2 ) = 11 Q ( S t + 1 , a 3 ) = 5 Q(S_{t+1}, a_3)=5 Q ( S t + 1 , a 3 ) = 5 TD Target = 2 + 0.9 ( 11 ) = 11.9 =2+0.9(11)=11.9 = 2 + 0.9 ( 11 ) = 11.9
TD Error = 11.9 − 10 = 1.9 =11.9-10=1.9 = 11.9 − 10 = 1.9
Updated Q ( S t , A t ) = 10 + 0.5 ( 1.9 ) = 10.95 Q(S_t, A_t)=10+0.5(1.9)=10.95 Q ( S t , A t ) = 10 + 0.5 ( 1.9 ) = 10.95
Q-Learning Algorithm
Loop for each episode: Initialize S Loop for each step of the episode: A t from S t using policy π derived from Q Take action A t + 1 , observe R t + 1 , S t + 1 Q ( S t , A t ) ← Q ( S t , A t ) + α [ R t + 1 + γ max a Q ( S t + 1 , a ) − Q ( S t , A t ) ] S t ← S t + 1 Until S is terminal \begin{aligned}
&\text{Loop for each episode:} \\
&\quad \text{Initialize} \quad S \\
&\quad \text{Loop for each step of the episode:} \\
&\quad \quad A_t \text{ from} S_t \text{ using policy } \pi \text{ derived from } Q\\
&\quad \quad \text{Take action} \quad A_{t+1}, \quad \text{observe} \quad R_{t+1}, \quad S_{t+1} \\
&\quad \quad Q(S_t, A_t) \leftarrow Q(S_t, A_t) + \alpha [R_{t+1} + \gamma \max_{a} Q(S_{t+1}, a) - Q(S_t, A_t)] \\
&\quad \quad S_t \leftarrow S_{t+1} \\
&\quad \text{Until} \quad S \text{ is terminal} \\
\end{aligned} Loop for each episode: Initialize S Loop for each step of the episode: A t from S t using policy π derived from Q Take action A t + 1 , observe R t + 1 , S t + 1 Q ( S t , A t ) ← Q ( S t , A t ) + α [ R t + 1 + γ a max Q ( S t + 1 , a ) − Q ( S t , A t )] S t ← S t + 1 Until S is terminal Cliff Walking
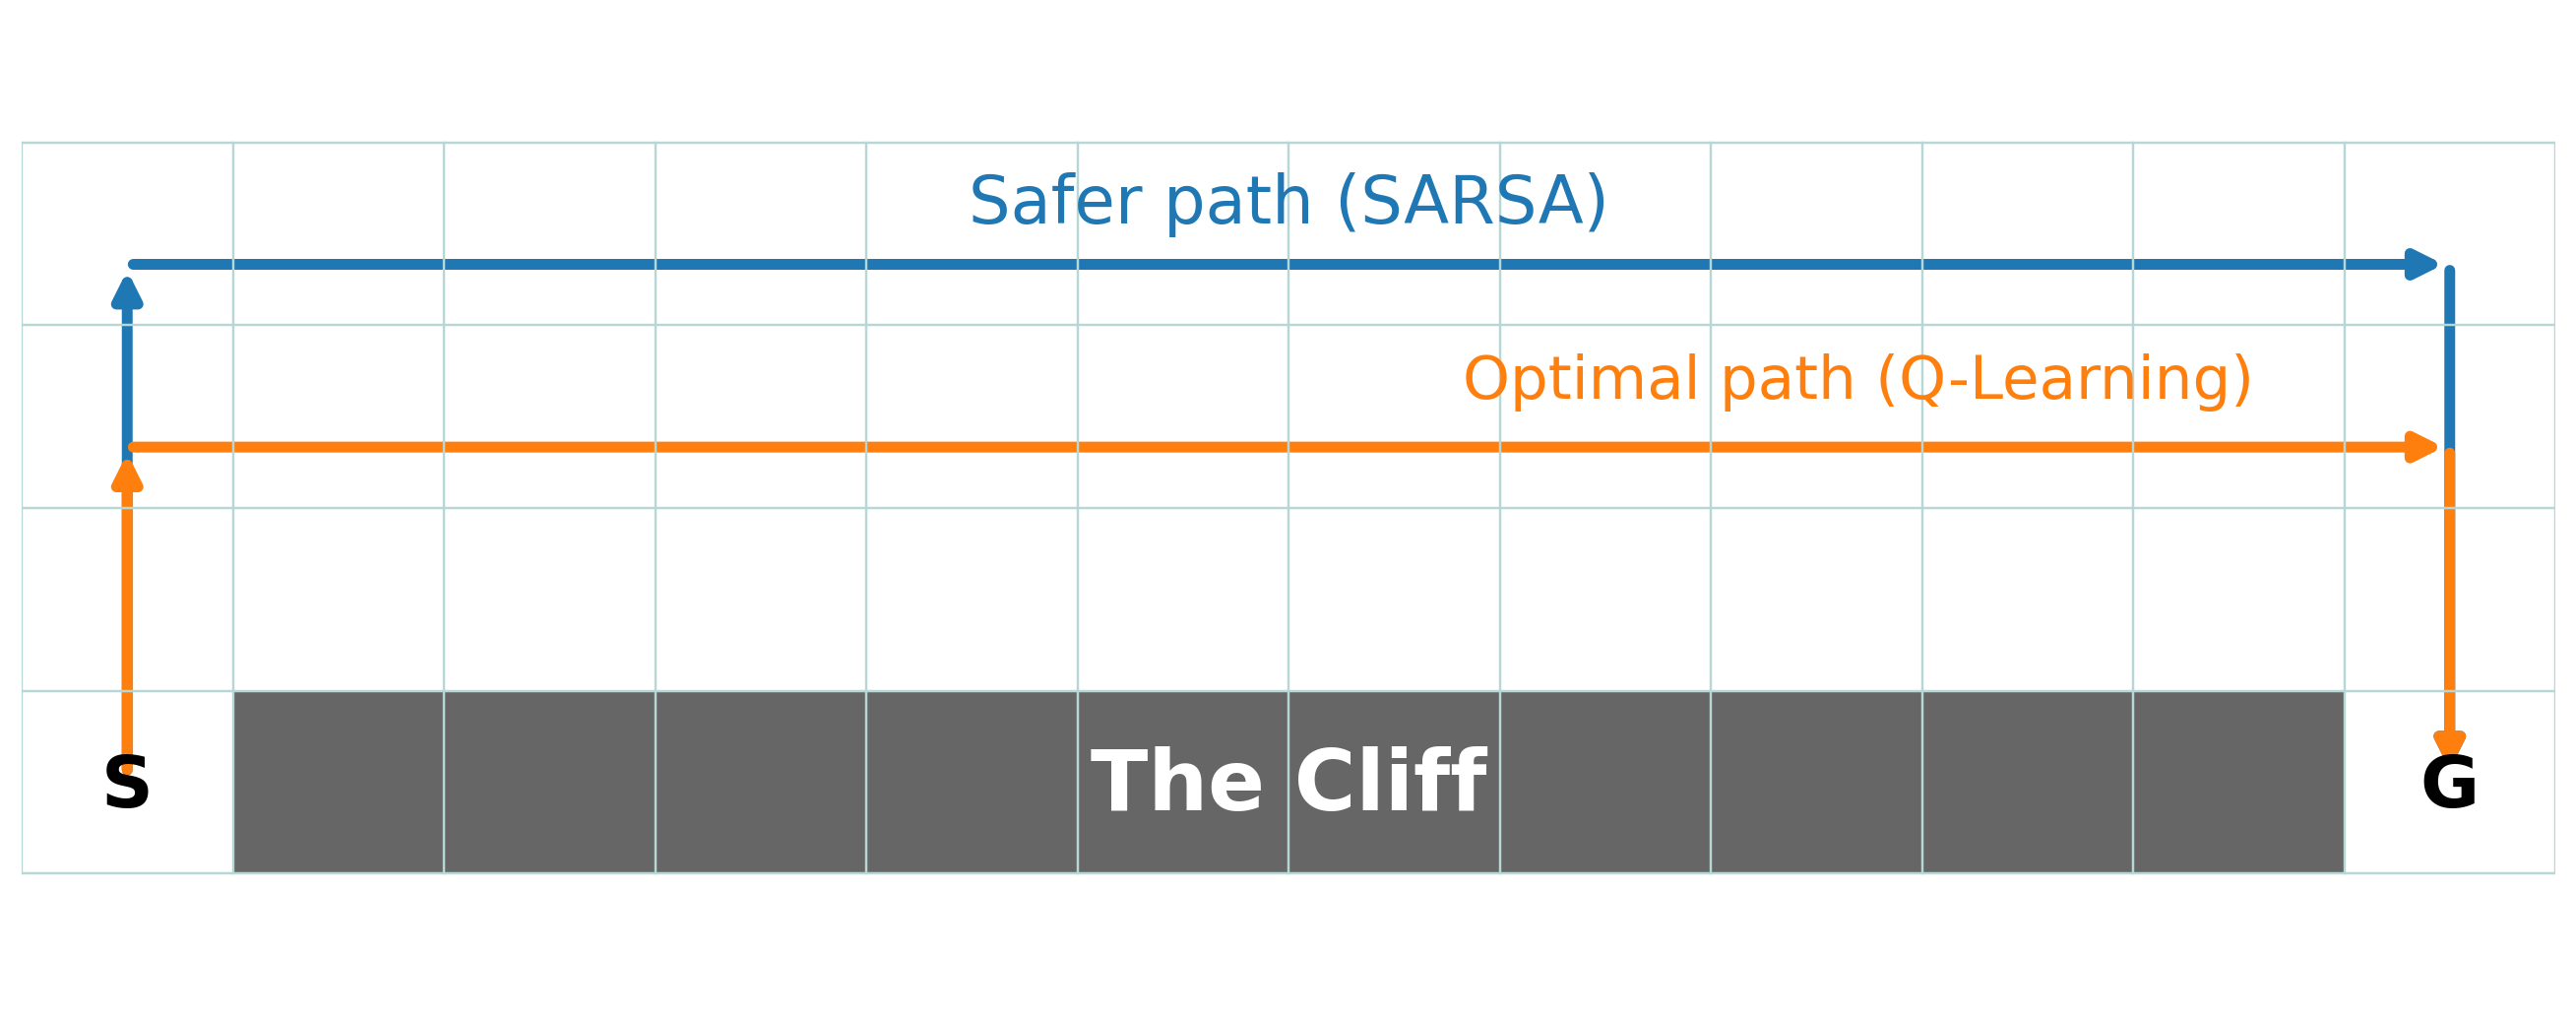
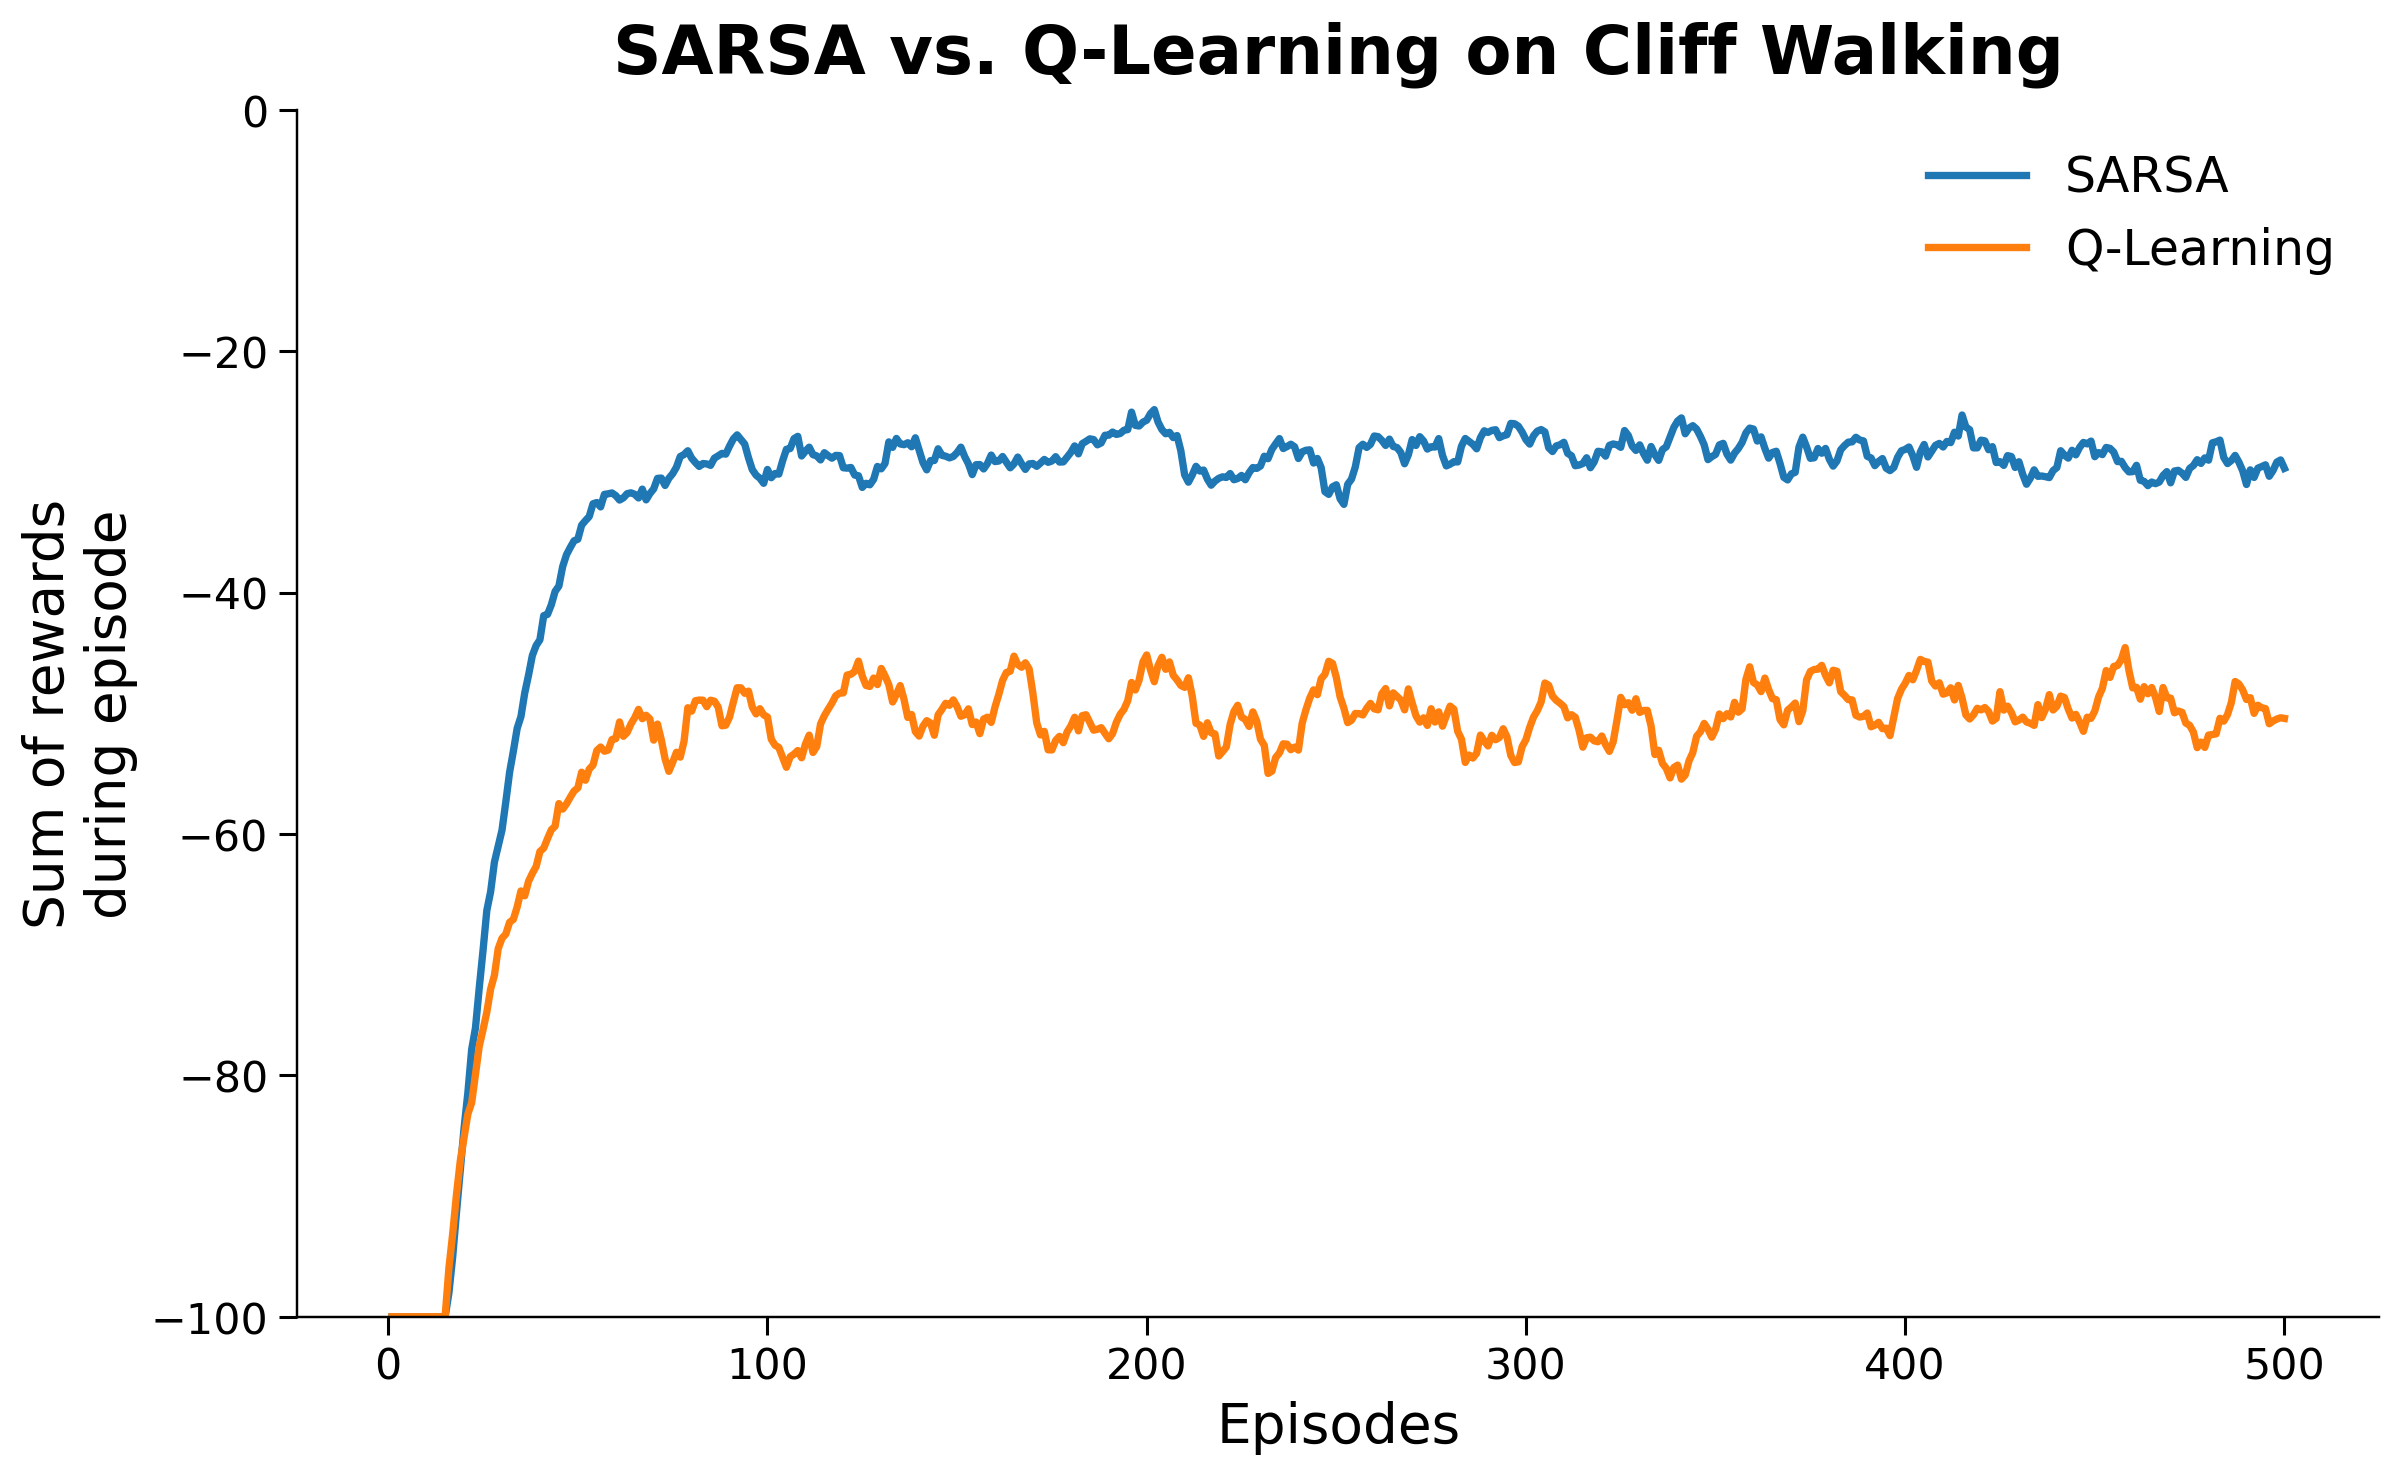
SARSA (on-policy) accounts for ε-greedy exploration near the cliff and learns the safer route.
Q-Learning (off-policy) learns the optimal route.
but occasionally falls off the cliff during exploration, hurting its online performance
Aspect SARSA Q-Learning Policy type On-policy Off-policy Bootstrap target Q ( S t + 1 , A t + 1 ) Q(S_{t+1},A_{t+1}) Q ( S t + 1 , A t + 1 ) max a Q ( S t + 1 , a ) \max_a Q(S_{t+1},a) max a Q ( S t + 1 , a ) Next action used Action actually taken Best possible action Learns Value of the behavior policy being followed Optimal policy π ∗ \pi_* π ∗ Cliff Walking Safer path Optimal but riskier path